Scumble dev blog
What was built, what was measured, and what did not work.
· v0.1.52
Green screen keying on your ComfyUI, and LoRAs
Scumble keys green and blue screens now, with CorridorKey 2.0 on your own ComfyUI: soft alpha for hair and motion blur, even on a 15,000 pixel picture. LoRAs come to your ComfyUI and Comfy Cloud recipes, MOSS-Image Edit and P-H3-Image join, GPT Image 2.6 arrives, and a lot of heavy pixel work got faster.
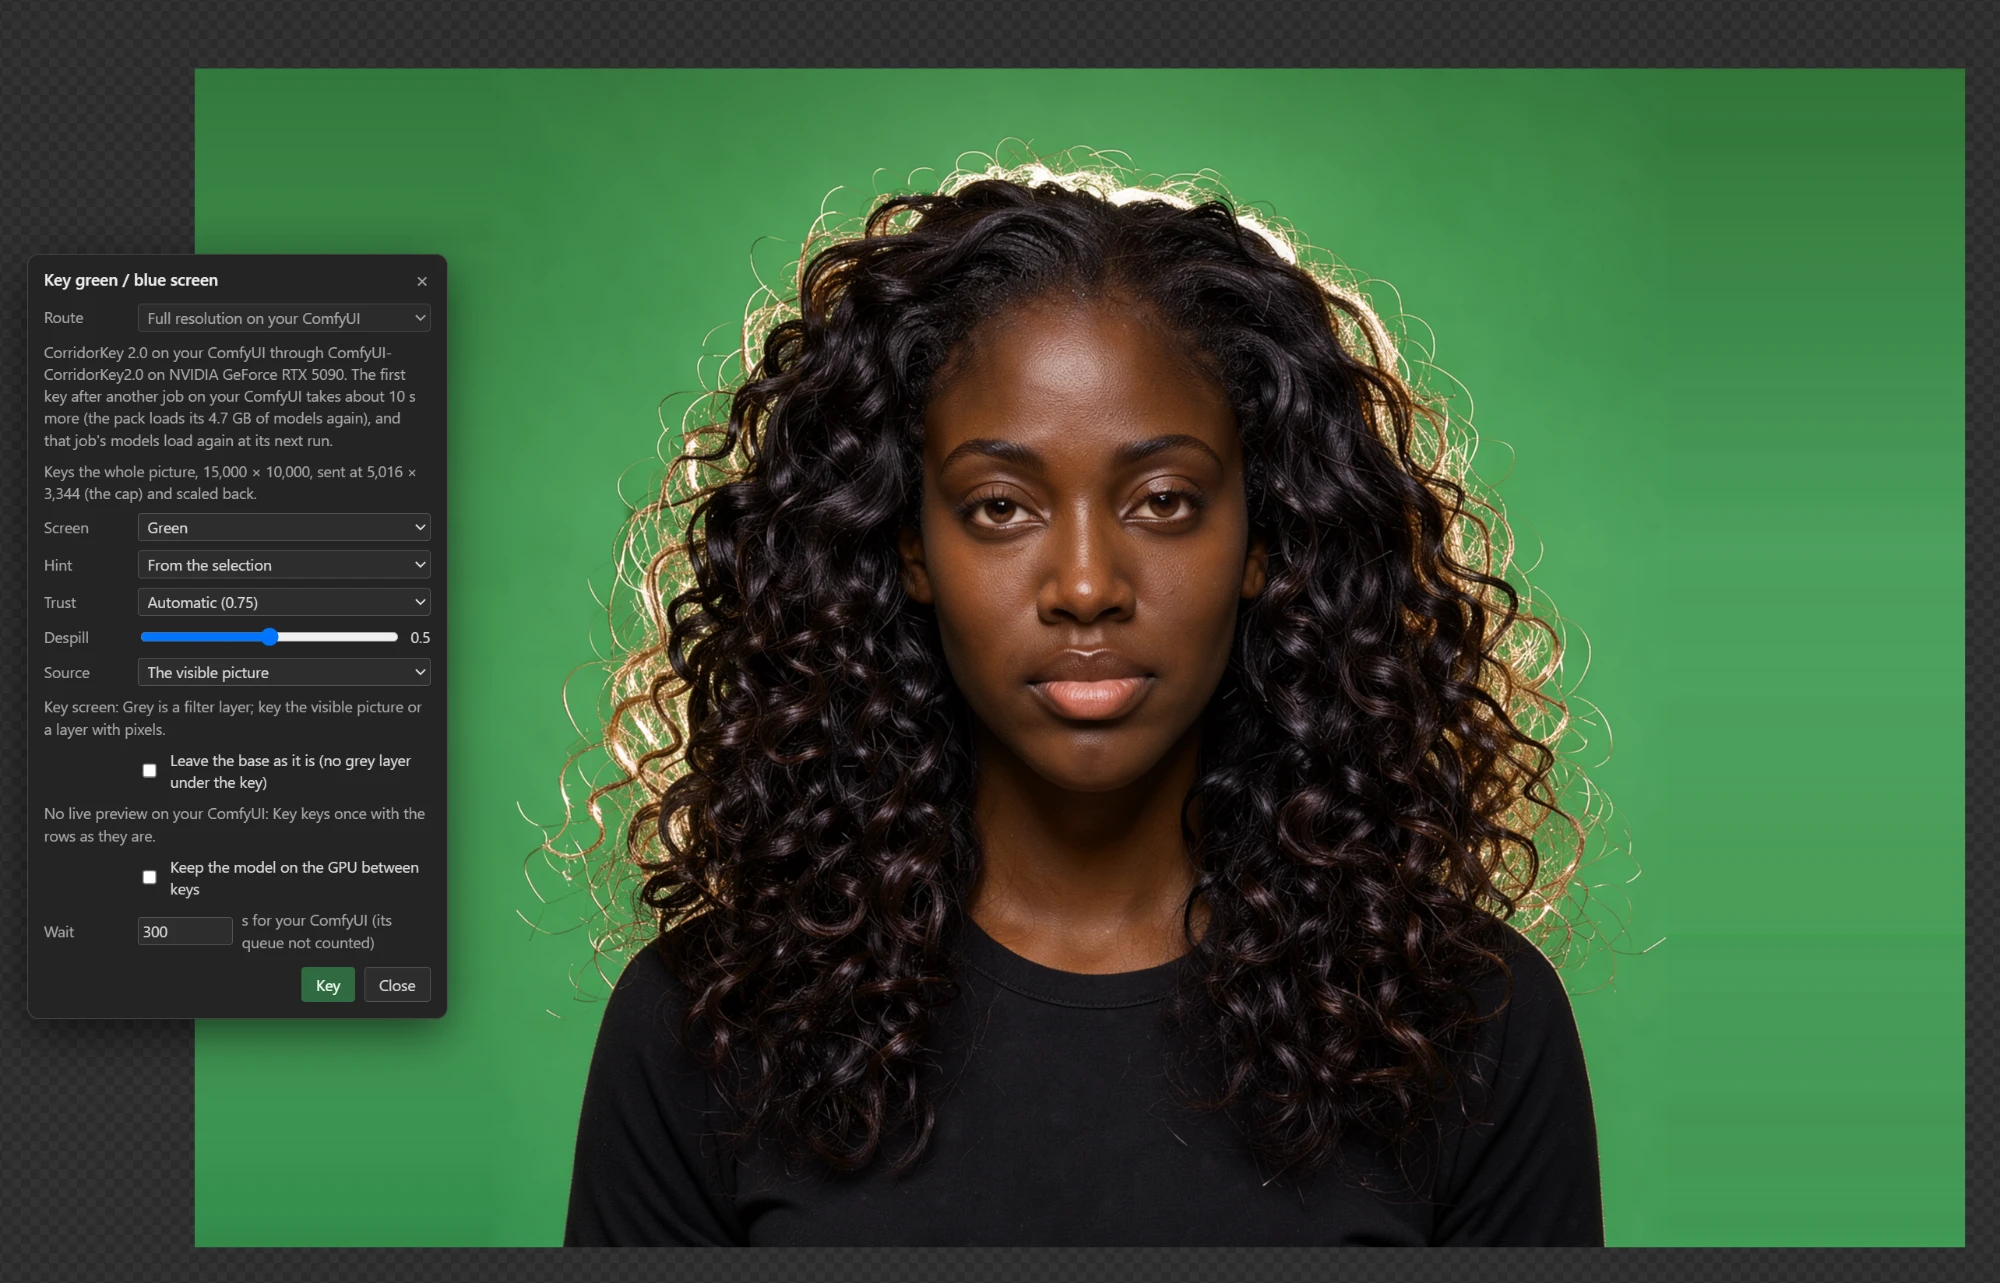
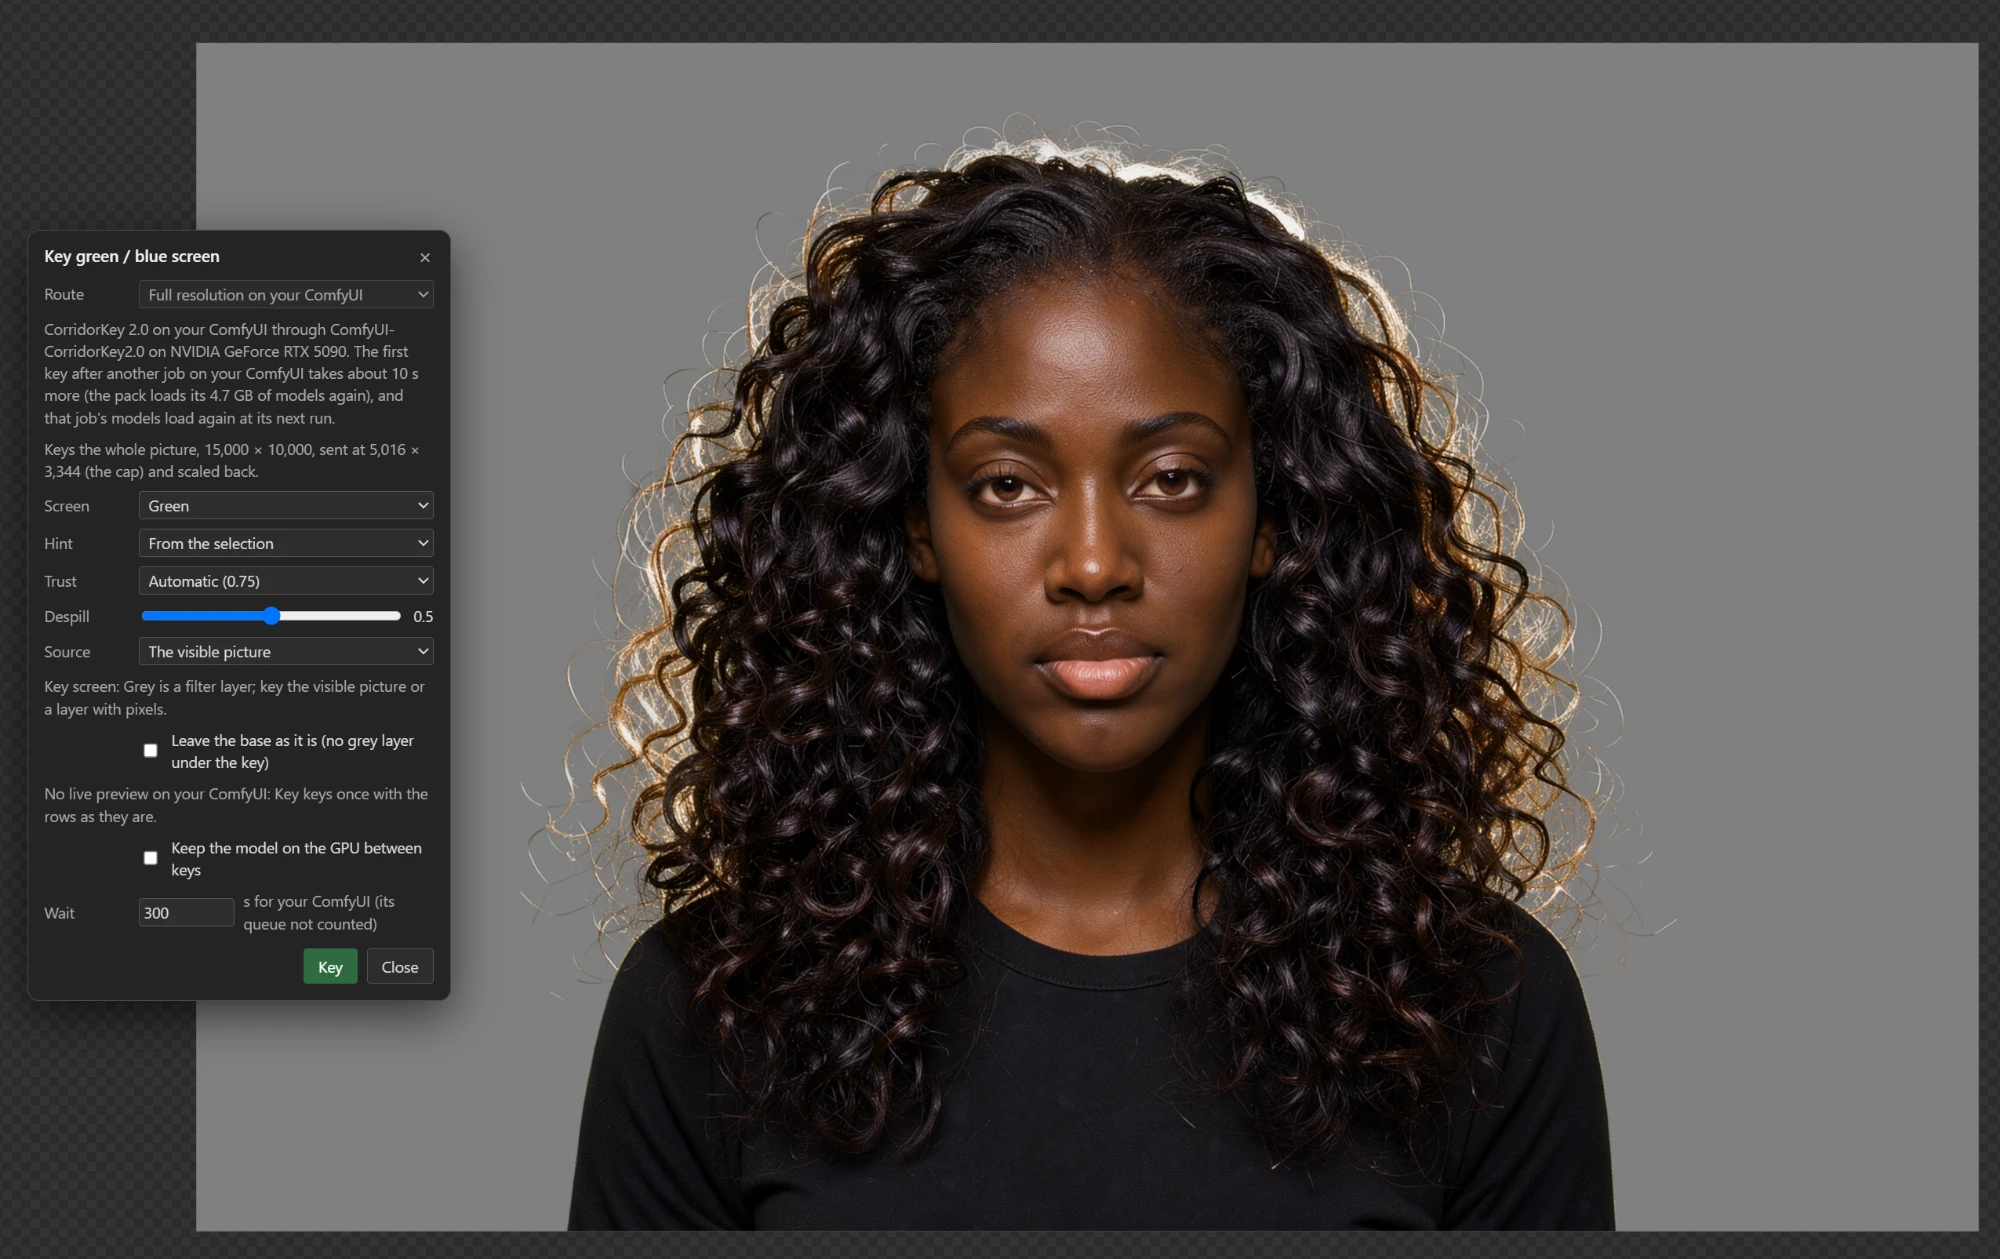
Release on GitHub ↗The big one is keying. Image, Key Green / Blue Screen cuts out a subject shot on a green or blue screen with CorridorKey 2.0 by Corridor Digital, and it does the part a selection never could: single hairs, motion blur and see-through edges keep their soft alpha, and the green that spilled onto the subject is taken out. It runs on your own ComfyUI through the community node pack ComfyUI-CorridorKey2.0, on an NVIDIA card of the RTX 30 generation or newer; the pack and its models, about 5 GB, live on that machine, and Scumble never downloads them. Corridor Digital said yes to using it in a free app, which is what made this possible, so thank you. Here is a 15,000 by 10,000 portrait keyed as a whole: Scumble sends it at the 16 megapixel cap, 5,016 by 3,344, and brings the matte back to full size, fitted to the picture's own edges. The key itself took under ten seconds on my card.
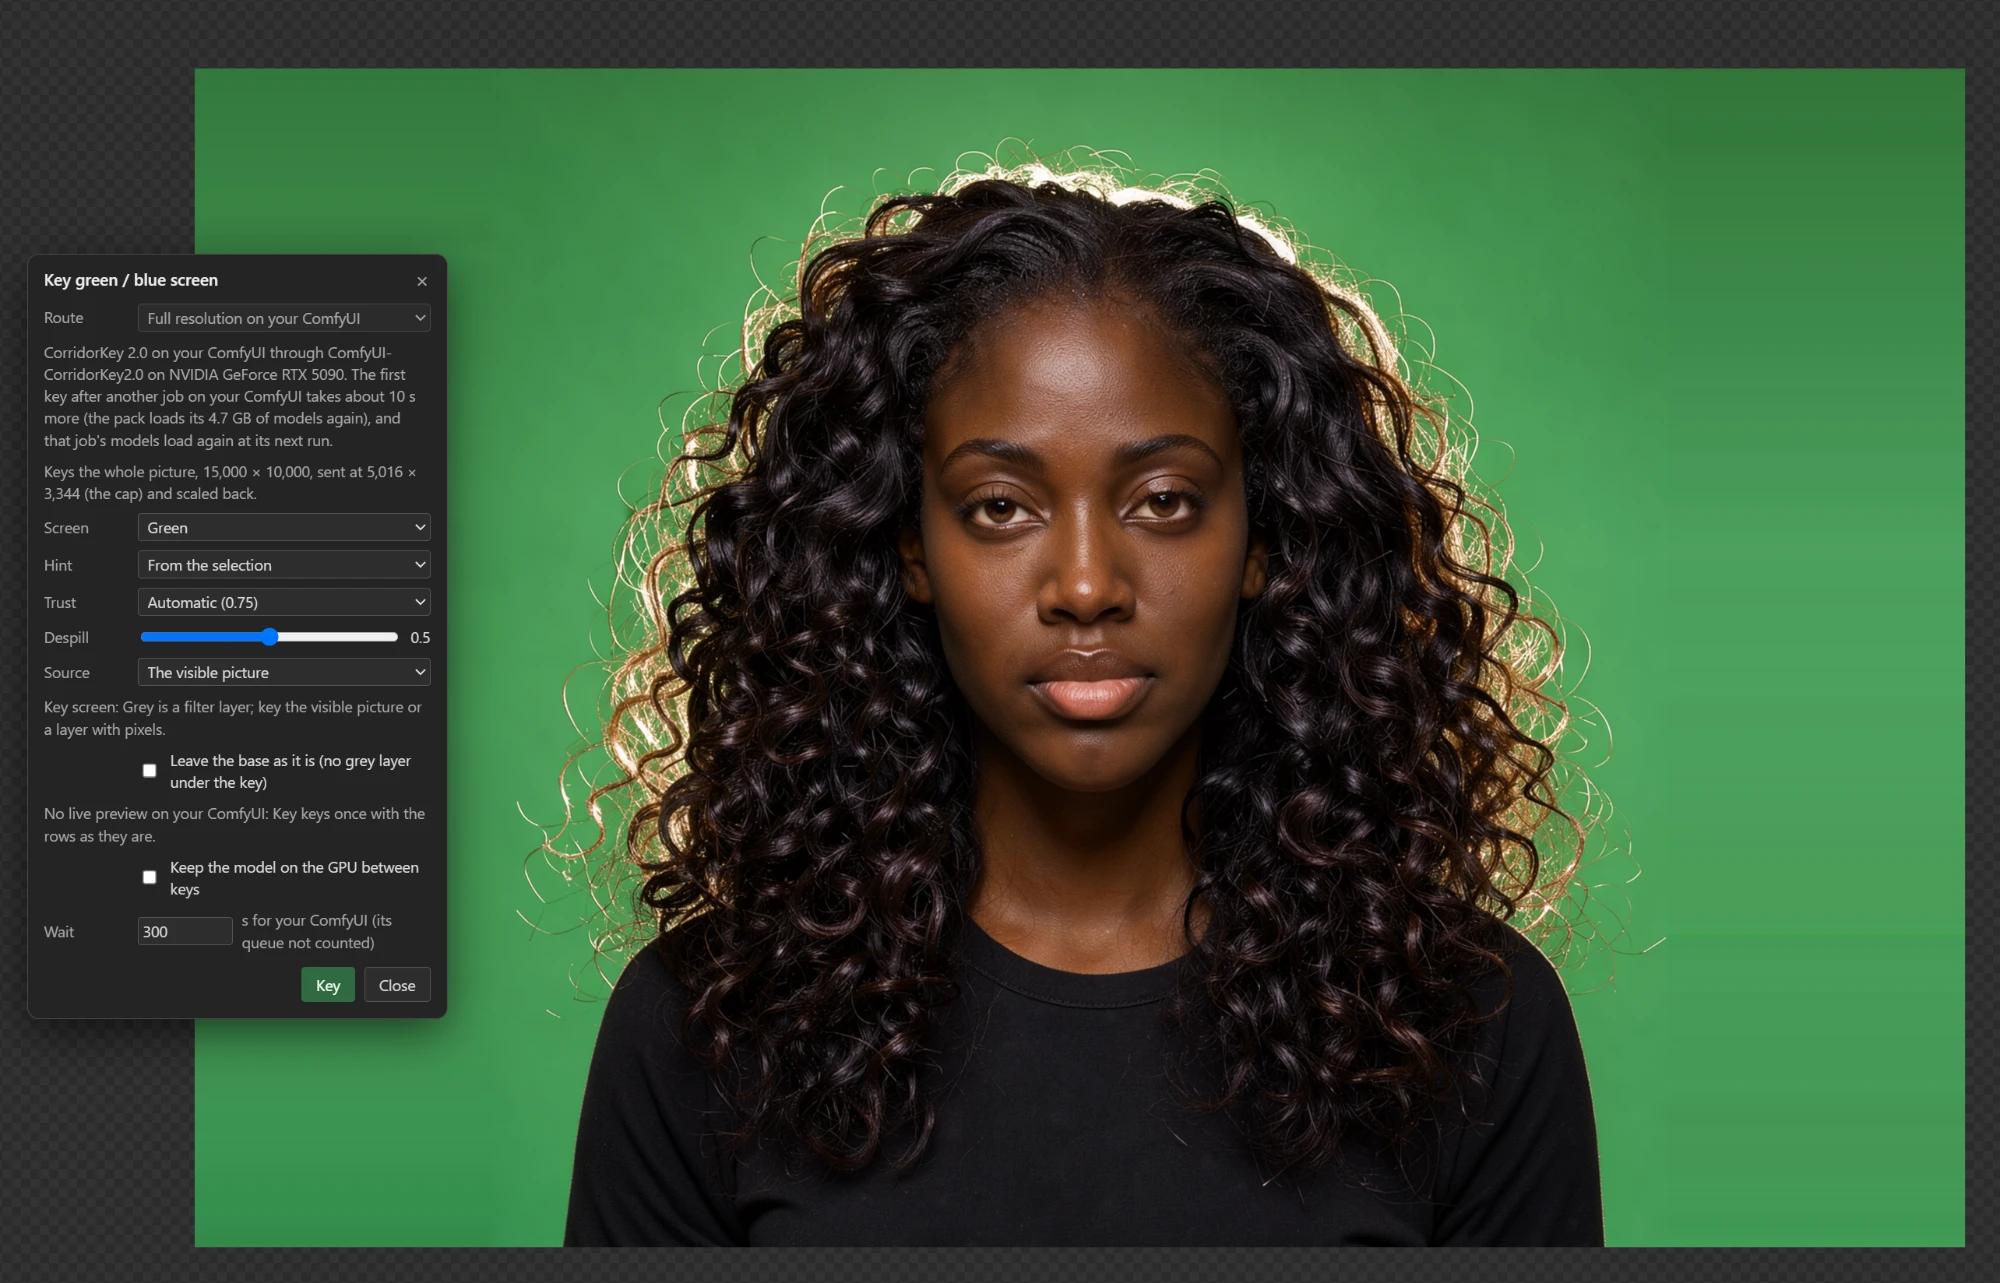
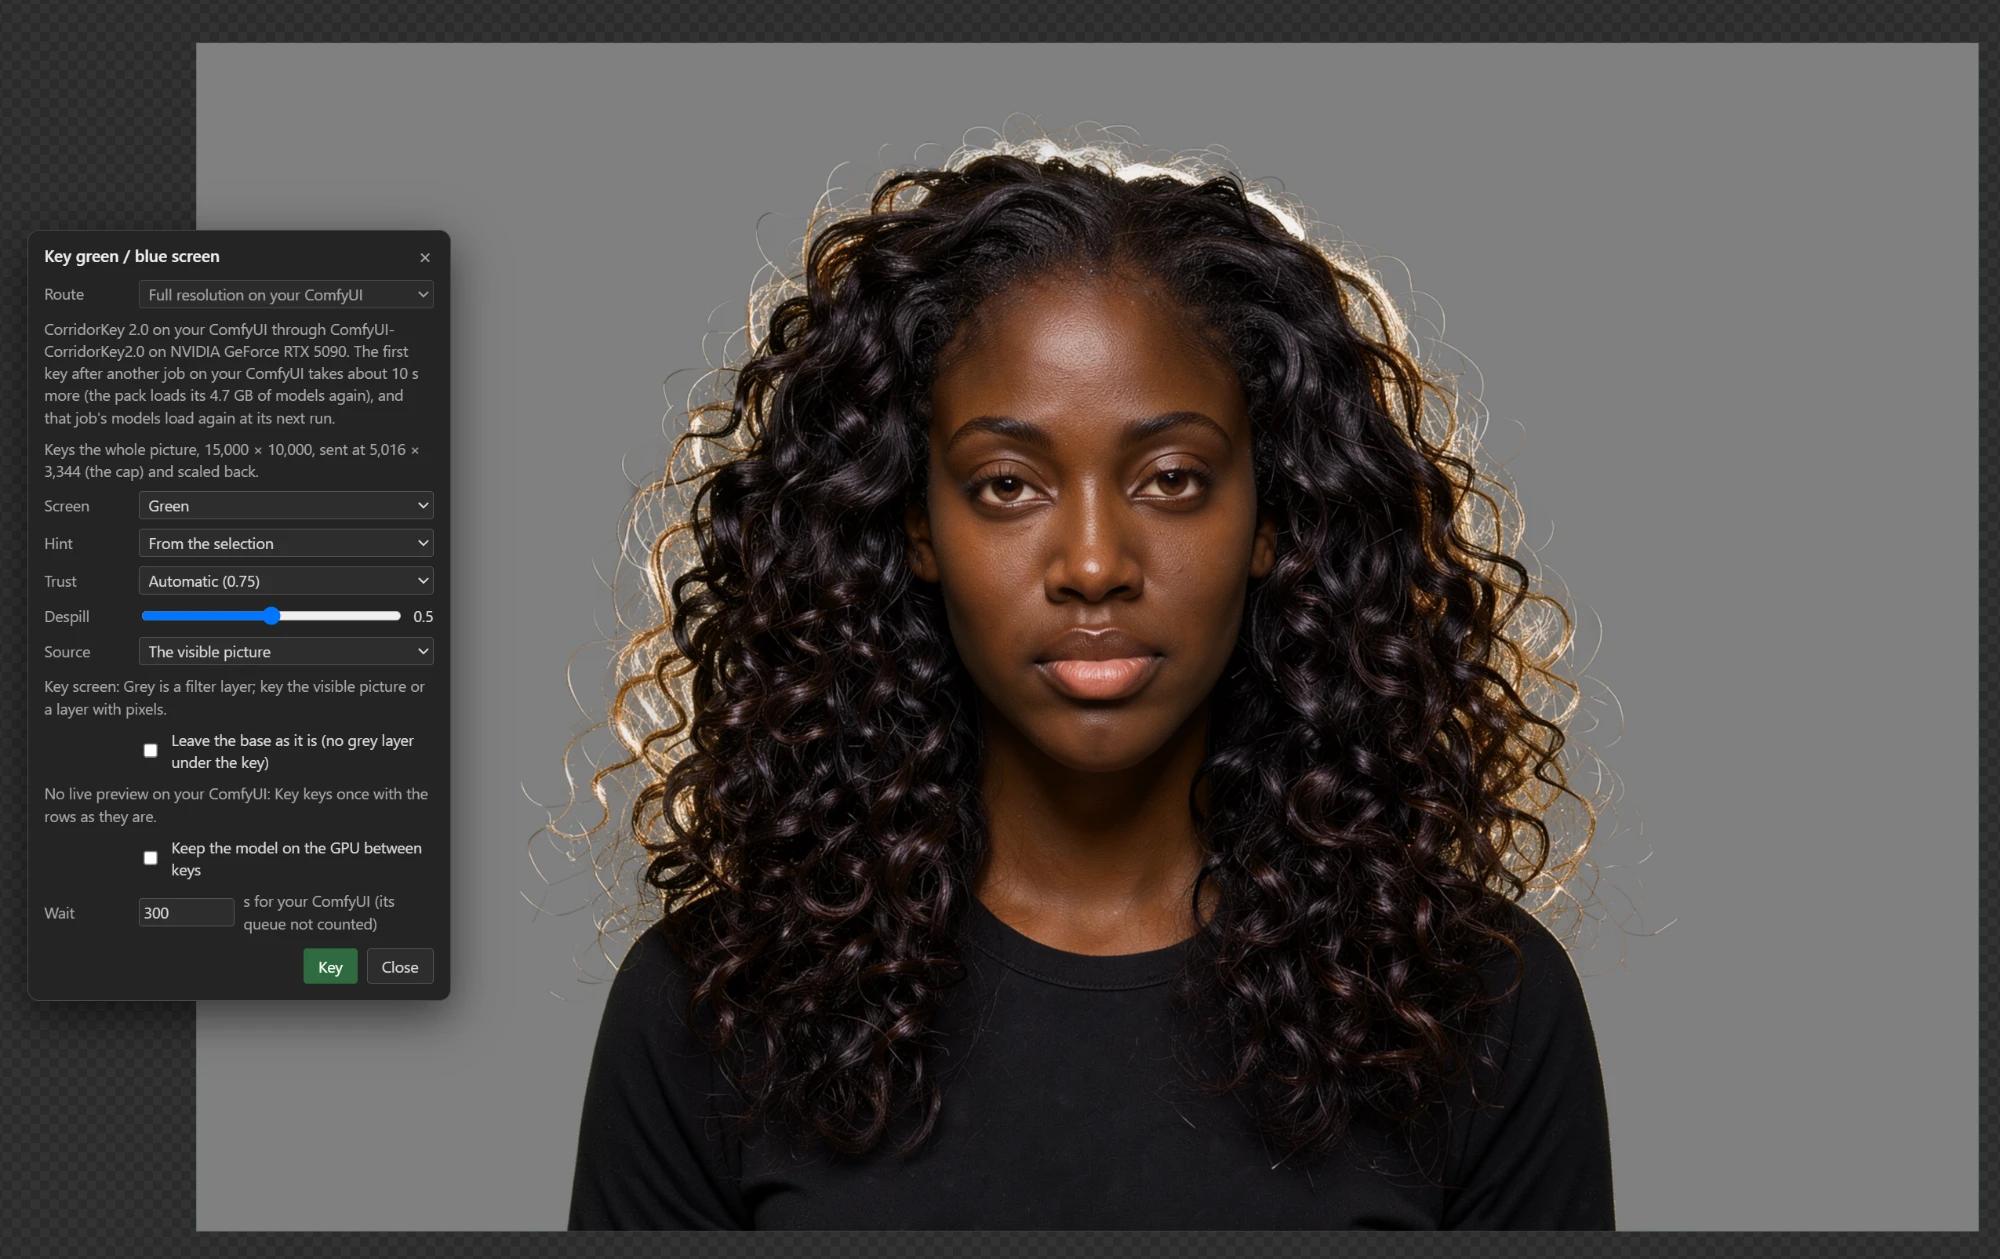
The answer lands as one Key layer with the subject's own colour and the matte as its mask, with a mid-grey layer under it so you can judge the edge, and one Ctrl+Z takes it all back. The selection is the hint: brush roughly over the subject or select it by text, and tell the dialog how much to trust it. With the Key layer active the dialog offers Re-key: paint the mask where the matte is wrong and it keys again from what you painted. After my first test run the dialog got a title bar to drag it by and a close button, because it sat right on top of the hair I wanted to look at. The first key after another job on your ComfyUI takes about ten seconds more while the pack loads its models; after that, a key of a normal-sized picture took about three seconds.
LoRAs were the other big ask, from a GitHub issue. Recipes on your own ComfyUI and on Comfy Cloud get a LoRAs section: up to five rows per recipe, each a LoRA from your server's list with a strength and an on and off tick, kept per recipe for every document. Scumble adds them to the graph when the run goes, so your recipes stay as they are. It also shows which base model a LoRA was trained for when it can read that, and warns when it does not match the recipe, because ComfyUI itself loads a wrong LoRA without a word. LoRAs never go to the API providers.
Three new models. MOSS-Image Edit, asked for in another issue, edits the selection by instruction on your own ComfyUI, with up to three more pictures, and on Comfy Cloud. P-H3-Image, Pruna AI's fast 8-step model on MiniMax H3, edits and makes new pictures on your ComfyUI, on Comfy Cloud and on WaveSpeedAI; its licence, the MiniMax H3 Community License, does not cover use in the EU, the UK, South Korea or the US without a separate licence from MiniMax, so read it before you use it there. And OpenAI's GPT Image 2.6 Sunburst and Flare came in a few days after their launch, with a new Complexity setting for how much the model plans before it draws.
Under the hood a lot got faster on big pictures, the start of moving more of the heavy pixel work into Rust. On a 15,000 by 10,000 picture, opening a large PSD stops the window for under two seconds instead of up to eleven, the magic wand holds it for about a tenth of a second, a PNG export takes 1.4 seconds instead of 1.9, and relight's shadows land 0.65 seconds after a light moves instead of 3.5, all with the same pixels as before. Helper model downloads are now checked against their published checksums, and your Hugging Face token only ever goes to Hugging Face.
Honest notes. Keying ran live on my own ComfyUI the night before the release: a green and a blue plate, a Re-key and the whole 15k picture; the two messages for a missing model folder and a missing node pack were only checked against a stand-in. GPT Image 2.6 is written from the providers' documentation and has not run against the live services yet, and P-H3-Image has only run on my own ComfyUI. Before the release a group of review agents read everything that changed since 0.1.51 and found six real problems, the worst a Generate new that could empty your picture before it refused a missing LoRA file; all of them are fixed. A version of keying that runs inside Scumble without ComfyUI is planned for a later update.
· v0.1.51
Big exports save again, and two new skins
A hotfix for a crash I found while measuring: saving an export of more than about half a gigabyte ended Scumble's window. Exports now go to the disk in pieces. And two new skins, Comfy and Black Forest.
Release on GitHub ↗I am working on a bigger update on a branch, more of Scumble's heavy pixel work moved into Rust, and that work starts with measuring everything at 15,000 by 10,000 pixels. One of those measurements saved its exports for real for the first time, and the PSD of that picture with one layer above it, about 0.9 GB, never reached the disk: Scumble's window ended, reloaded and brought the documents back from the autosave, but the file was not written. The released version has the same bug, so it gets a fix of its own now instead of waiting for the big update.
The cause was simple once I measured it. The window handed the whole file to the part of the app that writes to disk in one message, and one message of about 512 MB or more ends the window: 500 MB went through, 600 MB did not. Now an export goes over in pieces of 64 MB, each read on its own, so the size no longer matters. I saved that 15k PSD for real afterwards, 925 MB in four and a half seconds, and opened it again from the file.
While I was in there, saving got safer too. An export is written to a temporary file next to the target and only put in its place once every byte is there, the way a .scumble document already was. A save that fails, or a disk that is too full for it, leaves an older file of the same name as it was, and the full disk is said before anything is written. When another program holds that file open, a viewer for example, Windows refuses to replace it, so the export is written into it as before; links keep pointing at the new picture, and a read-only file is refused up front.
Then two new skins under Settings and Appearance. Comfy is a deep aubergine night with neon-yellow pill buttons, and the side panel's sections turn into rounded node cards with a little yellow socket on their edge. Black Forest is forest-night green with warm cream type, sage accents, a brushed texture on the bars and calm rounded panels. Both are only colours and shapes, drawn in CSS, with the system's own fonts.
Honest notes. The fix was checked by a group of review agents, who found ten more things, all fixed before the release, among them the viewer that holds the file open. The test suite now saves a 600 MB export through the app on both backends and reads it back byte for byte, and the guards of the new code were broken on purpose one by one to see a test fail: all but one did, and that one is written down. The two skins were polished pane by pane by two agents, but how they look is a matter of taste, so tell me what you think.
· v0.1.50
MOSS-Image with boxes, and FLUX 3 Klein that writes your prompt out
Two open models on your own ComfyUI: MOSS-Image makes new pictures and lays them out from your boxes, words included, and FLUX 3 Image Klein now runs with Black Forest Labs' prompt upsampler in front of it. Plus a fix for selection by text and a handful of quick wins.
Release on GitHub ↗Someone asked on GitHub for MOSS-Image with its JSON layout, and here it is. MOSS-Image is OpenMOSS's open text-to-image model, Apache-2.0, and ComfyUI 0.42 runs it with its own nodes, so Scumble now has a local recipe for it. It makes new pictures with Generate new. The nice part is the layout: with the Boxes switch on, every New box you draw goes to the model as an item of its layout and a Text box as words to render, placed in the picture's own pixels by ComfyUI's MOSS-Image Layout Prompt node. In my first test the word MOSS sat across the top of a poster exactly where I drew it, a red bicycle in the box at the lower left and a plant in the one at the right, twenty seconds for the picture on my card. MOSS-Image cannot edit a picture, so Generate on a selection says to use Generate new, and boxes that keep, move or remove something are left out with a note.
The second one is FLUX 3 Image Klein, which came in the last release. Black Forest Labs say Klein is not meant to run without its prompt upsampler, a language model of their own that looks at your picture and turns your few words into the detailed instruction the model was trained on. Their hosted API does that by itself, my local recipe did not. Now it does: when the upsampler's file is on your ComfyUI, the recipe runs it first, the crop and your reference pictures in the same order Klein gets them, and you see the start of what it wrote in the status line and all of it in the log. I typed a red paper lantern instead of the plant, the upsampler wrote two hundred words about the lantern, its glow and its shadow and everything that should stay, and Klein swapped the plant and left the rest alone, in fifteen seconds. On Generate new it writes a full caption for the canvas's shape. One switch in the Settings panel turns it off, and without the file the prompt simply goes as you typed it.
Black Forest Labs also renamed the Klein files when they published them, so the download links in the recipe pointed nowhere. They point to the published files now, and the recipe says that the repository asks you to log in and accept the licence first.
Selection by text broke for anyone with a current comfyui-rmbg: its SAM3 node now requires a model name, and Scumble did not send one. Scumble now fills in every input a helper node needs with that node's own default, so it works again, with older packs too. The Realism Pass recognises workstation graphics cards, which it refused because their names carry no generation number, and I sent a fix for the same name check to the node pack it uses.
Then the quick wins. A local Klein run that fails with ComfyUI's matrix-shape error now says in plain words that the text encoder does not fit the model, and which file would. The Realism Pass says in red when it changed nothing, which can happen on a card it does not really support. An export too large for one canvas is refused before anything is written, instead of an empty file. A document from a newer version that holds a kind of layer this one cannot show leaves it out with a note instead of silently. And a local run whose prompt names a reference picture that the node cannot load now stops with a clear error instead of shifting the other pictures' names. Agents got line height and letter spacing for text, Reopen Closed Tab, the relight models' settings and the Boxes panel's warnings, 116 tools now.
Honest notes. The quick wins were built by three groups of agents, each checked by another one and fixed once more, and every test ran green before the release. MOSS-Image and the upsampler ran live on my own ComfyUI, five runs in all. The Realism Pass's new check was never measured on a card where the pass really does nothing, and MOSS-Image has only run with the files I downloaded, not with the smaller ones Comfy's templates use.
· v0.1.49
Comfy's own SDK, a cancel that stops, and FLUX 3 Klein on your ComfyUI
Comfy Cloud and Comfy Router now run through Comfy's official SDK: jobs sent once, a progress bar per node, a Cancel that stops the job and paid pictures that come back after a crash. And FLUX 3 Image Klein on your own ComfyUI, with edits, reference pictures and boxes in the prompt.
Release on GitHub ↗Two things carry this release. The first is under the hood: Comfy Cloud and Comfy Router now run through Comfy's own official TypeScript SDK instead of code I wrote against their HTTP routes, and Comfy Cloud moved to Comfy's newer API. For you that means a picture Comfy already holds is not uploaded again, a job is sent exactly once under a key of its own, so a dropped connection can never start it twice, and the job tells Scumble how far it has got while it runs. The progress bar in the status row now shows the node a Comfy Cloud run is at, node 3 of 12, and fills as that node works. About names the SDK and its version.
Cancel finally means cancel. Pressing it during a Comfy Cloud or Comfy Router run asks Comfy to stop the job, and the status line tells you how it ended: Comfy took the stop, the job had already finished and is charged, it had ended without a picture, or it had not gone out yet and nothing runs. Closing a tab stops the runs in it and says so before you close it. And a paid picture no longer gets lost: if Scumble crashes, is closed, the window is reloaded or a download fails while a Comfy Cloud job runs, Scumble keeps a note of the job and opens its picture as a document of its own as soon as Comfy has it, at the next start or in the same session, without ever sending the job a second time. A Wi-Fi that needs a minute to come back after the laptop wakes up no longer ends a run either.
The second thing is FLUX 3 Image Klein on your own ComfyUI. Black Forest Labs put the open Klein model out, ComfyUI 0.41 runs it with its own nodes, and Scumble now has a local recipe for it: it edits your selection with up to three more pictures, the Original and your reference layers, named in the prompt with @img1, and Generate new makes a picture from the prompt alone. The step-distilled model needs 16 steps, five to nine seconds a run on a fast card. One thing I learned while testing it: Klein only treats the crop as something to edit when the prompt says so, so the recipe wraps your prompt into an instruction for the picture and adds that everything else stays as it is. Without that it happily painted a whole new scene.
And Klein takes boxes, locally. The boxes you draw with the Boxes tool now also go to a recipe on your own ComfyUI: the Inpaint Canvas node writes them into the prompt the way FLUX 3 reads them, and the model puts things where the boxes say. In my test a black cat sat exactly in the box I drew next to a bicycle. For that you need the Inpaint Canvas node from GitHub, because the version on the Comfy Registry is older; Scumble tells you before anything is sent if your node cannot do it. FLUX 3 is a model I like a lot, and seeing it run on my own card with boxes in the prompt was the best moment of the week.
Smaller things. Every result now says where it ran: FLUX 3 Image via Comfy Router, 23 seconds, or via your ComfyUI, in the status line and in its row of the history. Reference rows can be dragged into a new order, and the @img tokens in the prompt follow their pictures. When no ComfyUI runs at the address, the top bar shows a calm grey dot and No ComfyUI running instead of a red error. The mascot sits next to the name in the title row and in About. Agents can relight with one of the eight light presets by name. Dragging a layer row onto the prompt field by mistake no longer writes its id into your prompt. A result that Scumble lines up with the picture's edges no longer smears a band of repeated pixels along the border, a bug I only saw on a real run. And RTX Video Super Resolution works again on Comfy Cloud and on your own ComfyUI, where the node now needs two more settings; on your machine it also needs a newer nvidia-vfx, which comes from NVIDIA's own package index.
Honest notes. Before the release a large group of review agents read every change of this update and a second group checked each finding; between them they found 48 real problems, one of them serious, and all are fixed. Then I ran the paid checks myself: a picture and an edit on Comfy Cloud, a cancel in the middle of a run, and a FLUX 3 Image edit through Comfy Router on the new SDK, all of it for a few cents. The other Comfy Cloud and Comfy Router routes have not run through the SDK against the live services yet. Next up is MOSS-Image with its JSON layout, which someone asked for on GitHub.
· v0.1.48
Status and feedback: red errors, a progress bar, your prompt back
A release about the line at the bottom of the window. Errors and missing downloads show red and blink, a thin bar follows every run, a click on a result's prompt puts it back in the field, and an upscale too large for one canvas is refused before you pay for it.
Release on GitHub ↗This release is about the status line at the bottom of the window. For a long time an error looked exactly like any other message there: same colour, same place, easy to miss while you were looking at the picture. Now an error, a model that still has to be downloaded, a size a run would pass or a result that came out only in part shows red, blinks five times and then stays red until the next message. Hints like select a layer first stay plain, because they are not mistakes. With the system's animation effects turned off the line is red without blinking. Agents can mark their own messages the same way through set_status, and plugins through their status call.
Next to that line there is now a thin progress bar. On your own ComfyUI it follows a run node by node and shows a sampler's steps and the seconds, for a Generate, the Realism Pass, relight and an upscale of the whole picture; through an API provider it counts the seconds you have been waiting. Every tab has its own bar, and a second Generate queued behind the first is counted. The bar and the next thing were asks in an issue on the node's GitHub, and they were good asks.
The other ask was getting a prompt back. Every result in the history now keeps the prompt it was made with, even when you kept typing while it ran. Click the prompt under a result and it goes back into the prompt field, Revert brings back what you had, and Ctrl+click copies it. Its @img tokens follow the reference layers.
Then sizes. Some upscalers go very large, and a whole-picture upscale whose answer would be bigger than one canvas can hold, 65,535 pixels a side or 268 megapixels, used to be paid for and then fail to land. Now it is refused before anything is sent, and the message names the largest factor that fits. A model that picks its own factor and answers too large lands scaled down to fit, and Resize and Extend refuse such a size instead of making an empty picture.
Smaller things. With two Generates queued in one tab, the first result could land in whichever tab was in front; it lands in its own tab now, and closing a tab while its render runs asks first. The Help shows the manual's italics as italics. And if you open the developer tools, the console greets you with the Scumble mascot in ASCII, printed at every start by a tiny Brainfuck program. It is silly, and I like it.
Honest notes. Before building the release I let a group of review agents read every change since 0.1.47, and then a second group try to break the fixes. Between them they found fifteen small things, none serious, all fixed: the bar could lose a run after a long network drop, a closed tab's result could land in another tab, a Magnific Precision factor like 5.5 would have gone out as 6, and Magnific Creative's 25.3 megapixel limit was only checked after the upload. The progress bar is in the app only for now; the ComfyUI node will get it later.
· v0.1.47
Relight: new lights for an old picture
A filter layer that lights the picture anew from its depth map: up to four lights you drag on the canvas, points, spots and the sun, with soft shadows and highlights that roll off into white. Presets, gloss and gobos, and a way to hand your lights to a model when the app's own light is not enough.
Release on GitHub ↗This one is a single feature, and it took longer than anything before it. Relight is a filter layer that puts new lights into a picture. It reads the depth map from 0.1.44, turns it into a little height field with surface directions, and shades the picture with up to four lights: a point light, a spotlight with a cone and a soft rim that you aim with a second handle, or the sun. Each light has a colour temperature, seven presets from tungsten to blue sky or a colour of your own, an intensity, a softness and a distance, and each one casts soft shadows over whatever stands between it and the surface.
You work with the lights on the canvas. The Lights tool, L, shows a handle for every light; drag it and a quick preview follows the pointer, Alt-drag brings the light closer or pushes it back, the mouse wheel makes it softer and Shift with the wheel makes it stronger, the arrow keys nudge it, a click adds a light and Delete removes one. H hides the handles when you want to look at the picture alone. A grey ring shows where Scumble thinks the picture's own light comes from, and the Original light slider fades that light down, so a new light from the other side does not fight the old one. Ambient keeps the deepest shadows readable, Depth sets how deep the scene is, Shadows how dark they fall.
Around that there are eight presets, studio portrait, warm sunset, cyberpunk neon, Rembrandt, soft window, dramatic rim, golden hour and film noir, each fitted to your picture in one undo step. Every light has a Gloss slider for highlights on wet skin, eyes and shiny things, and a spotlight can throw a pattern: blinds, a window, leaves or stripes.
Sometimes the app's own light is not enough, because a real relight changes how materials respond and that is what models are good at. So a Relight layer can also render through Magnific Relight, which gets your picture and a map of your lights, through fal's IC-Light v2 and Bria relight, or through Qwen Image Edit 2509 with a relight LoRA on your own ComfyUI or on Comfy Cloud. Render lands the answer as a pixel layer under the Relight layer and hides the Relight layer, in one undo step, so you can move a light and render again. Detail from original keeps your picture's fine texture under the model's new light, up to 27.9 megapixels. Agents get a relight command; the assistant uses the app's own light by itself and asks before a paid render.
The last thing went in on the morning of the release. With a strong light, bright parts of the picture used to clip flat at white. Now they roll off softly into white, and everything a light does not touch keeps its exact value. The Layer menu is new too: New Relight Layer is there, and New Dodge and Burn Layer moved over from the Image menu.
Honest notes. Relight went through three rounds of review and then four sessions of fixes before I was happy with it; most of what those found was in the tests, which passed while checking nothing, and some of it was real: an undo that ran over edits made while it waited, a quick drag preview that a render could pick up instead of the full shadows, and a LoRA that was sent at one percent of its strength. The routes through Magnific, fal, Comfy Cloud and the local Qwen recipe are built from the providers' documentation and tested against stand-ins; I have not run them against the real services yet. The local route needs the Qwen Image Edit 2509 checkpoint and both LoRAs on your ComfyUI, and the recipe links them. Documents with a Relight layer need 0.1.47 or newer.
· v0.1.46
Seventeen blend modes, lens blur, and a New that knows your model
The fourth part of the filter work: every blend mode you know from layer editors, dissolve included, the same on screen, in an export and in a PSD. A lens blur that reads the depth map, four quick adjustments, a New dialog that makes the canvas your model will answer in, and Qwen's 8-step Turbo on your own ComfyUI.
Release on GitHub ↗Blend modes first, because there are a lot of them now. Next to the nine Scumble had, there are colour burn, linear burn and darker colour; colour dodge, linear dodge and lighter colour; vivid light, pin light and hard mix; exclusion, subtract and divide; hue, saturation, colour and luminosity; and dissolve, which keeps a random share of the layer's pixels, as many as its alpha and opacity say, fixed in the picture so they do not crawl when you pan. The list in the layer row is grouped by what the modes do, darken, lighten, contrast, inversion and component, which makes it a lot easier to find the one you want. Every mode is computed the same way on screen, in an export, in a merge and in a run, and PSD files keep them in both directions, so a PSD from another program no longer opens with half its layers set to normal.
Lens blur is a filter layer that blurs the picture by its depth map the way a lens does. You set the focus depth, how much around it stays sharp, and the aperture, up to 1.5 percent of the picture's long side; bright highlights out of focus open into round discs, as much as you want them to. A blurred foreground falls off softly over a sharp background, and a sharp subject keeps its edge instead of being eaten by the blur behind it. It runs on the graphics card, and what you see at any zoom is what the export writes.
Four small adjustments came along: vibrance, which lifts muted colours more than saturated ones and leaves skin alone; a gradient map with six presets or two colours of your own; threshold; and posterize. Nothing fancy, but I kept reaching for them.
The New dialog learned something I wanted since the boxes went into FLUX 3. Pick a model, its provider, an aspect from that model's own list and a size class, 1k, 2k, 4k or whatever the model calls them, and New makes a canvas in exactly that shape to draw on. The document remembers the choice, so Generate new opens on the same model, aspect and size, and if you have drawn boxes and pick another aspect, it tells you the boxes would go stretched instead of quietly stretching them. Generate new now offers each model's own aspects and names its size classes the way the model counts them. Agents get the same through new_canvas and generate_new.
For local users there is a recipe for Qwen Image Edit 2.1 Turbo, Qwen's 8-step checkpoint, on the same edit chain as the full model with up to ten pictures. On my card a run takes about five seconds once the model is loaded. The recipe links the file it needs. And winget install scumble now installs the Microsoft Store version, no product ID to remember.
Honest notes. While reviewing this release I found that haze, and the lens blur too, had never actually run on the graphics card: a registration failed quietly at start-up and everything fell back to the processor, while the test that should have caught it compared the processor with itself. Both run on the GPU now, and haze on a big picture is a lot faster than it was in 0.1.45. Hard mix now decides the exact middle the way the big editors do, checked against a reference file pixel by pixel. Documents with the new blend modes or filter layers need 0.1.46 or newer. New with a model has been tested in the app and by the gates; a real FLUX 3 run with boxes on such a canvas is the next thing I will try.
· v0.1.45
Colour grading, HSL, glass and haze, and a one-click Claude Desktop extension
The second and third part of the filter work land together: colour grading with wheels, HSL in eight channels, control points of any shape, an Effects pack with chromatic shift and glass, haze and dehaze on the depth map, and the depth tools that make all of it stick to contours. For agents, Scumble now installs into Claude Desktop with one click.
Release on GitHub ↗This is the biggest version so far, and it is two releases in one. After the depth map of 0.1.44 I decided to build the next two parts of the filter work as one block and release them together, so here they are. The first is colour. Colour grading is a filter layer with four wheels, shadows, midtones, highlights and the whole picture, each with a puck for hue and saturation and a brightness slider, plus Balance and Blending where the tonal ranges meet. HSL in 8 channels does what the name says: hue, saturation and luminance per colour, red, orange, yellow, green, aqua, blue, purple and magenta, with transitions smooth enough that neutral greys stay where they are.
Control points learned shapes. They were circles; now they can be oriented ellipses, closed polygons with three to sixteen corners you drag, or graduated lines that run from no effect to full effect with handles for feather and angle. Every shape has a softness slider for its edge, and Escape drops the active point. You can also copy control points and paste them on another picture, scaled to it, with their colours sampled again, and the same goes for masks: Copy mask, Paste mask from, in the mask menu.
There is a second built-in plugin now, the Effects pack. Chromatic shift fakes the colour fringes of a lens, as three plates 120 degrees apart, as lateral dispersion from the centre, or as a linear shift in one direction. Glass displacement refracts the picture through ribbed ridges, reeded lenses, wavy corrugations, blocks, frosted glass or pebbled cells, with a specular sheen and an optional frost blur. All of it is a filter layer, so it masks, limits and blends like everything else, and it runs on the GPU; a 15k picture exports a glass layer in about a second and a half.
The depth map got the tools it needed to be useful on real pictures. Selections by depth and depth-limited layers now snap to fine contours, hair, foliage, the edge of a silhouette, with an Edges slider that sets how far the colour guidance is trusted. Haze adds atmosphere that grows with distance, sampling the airlight from the far end of the picture or taking a colour you give it; Dehaze does the opposite, from the picture itself or from the depth map, with a Protect sky switch. When the map is wrong in a spot, select the spot and press Flatten, Nearer, Farther or Smooth. Large pictures can run a Fine or Finest detail pass, and any grey layer can become the depth map.
Two smaller things you will notice. Hover over a preset in the Film looks panel and the picture shows it before you click; every list in a filter row has a small button that does the same for its choices. And a bug that bit a Qwen user is gone: when a local recipe named a model file your ComfyUI does not have, the Settings row quietly took the first file of the folder, a Flux file on most installs, and the edit came back unchanged. The row now keeps the recipe's file, marked as missing, and Generate tells you where to download it.
For agents, the release carries a .mcpb file: open it and Claude Desktop installs Scumble's MCP server with one click, finds your installed Scumble by itself, and drives the window you are looking at. It took one evening longer than planned, because Claude Desktop runs extensions in a way that swallowed the first version's answers; the fix and the reason are in the repo for anyone who ships a desktop app this way.
Honest notes. Documents with the new layers need 0.1.45 or newer to open. The Effects pack and the grading wheels have been tested against their CPU twins and on my pictures, not by anyone else yet. Plugin authors get API 4: whole-picture statistics, colour and hidden parameters, and a way to roll a preview back.
· v0.1.44
Depth, range selections and filter limits
Scumble now computes a depth map of your picture in the app and puts it to work: select what lies between two depths, limit a filter layer to a range of depth, brightness or colour, let a haze grow with distance. With it come mask views, a box for the Object tool and soft selection combining everywhere.
Release on GitHub ↗This one is about depth. Selection, Depth computes a 16-bit depth map of the picture inside the app, with Depth Anything V2 Small, a 99 MB model you download once from Settings, Helpers; it runs on the GPU through DirectML or on the processor. The model itself sees the picture small, then a guided filter brings the map up to the picture's own size, up to 4,096 pixels on the long side, so its edges follow the picture's edges; a 15,000-pixel picture takes about a second on my card. The map is saved with the document, it follows turns, crops and resizes, and its row tells you when the picture has changed enough to compute it again. It never recomputes on its own, because you may well like the one you have.
The first thing the map is good for is selecting. The Selection panel has a new block, Select by range: pick depth, brightness or colour as the source, drag the two edges of a box over the picture's own histogram, pull the soft ends out from the strip below as far as you like, and the canvas shows a live tint of what you are about to select. Replace, add, subtract or intersect, and an Invert switch for the other side. The brightness and colour sources need no map at all, so the block is useful before you ever compute one.
The second thing is limits on filter layers. Every filter layer, and every fill layer, has a Limit row now: the layer acts only where the picture lies in a range of depth, brightness or colour, again with soft ends, and the painted mask still refines it on top. A fill layer with a depth limit is a haze that grows with distance; a levels layer with a brightness limit lifts the shadows and nothing else. Blend modes and opacity apply to the limited result alone, so a multiply layer leaves the rest of the picture exactly as it was. Documents that carry a limit open in 0.1.44 and newer; older copies say so instead of guessing.
To see what a mask or a limit is doing, Alt+click the mask label of a layer: the mask alone, black and white, until you Alt+click again. The mask menu has a red overlay over the picture instead, and a limited filter layer can show where it acts as a grey picture of its weights. All three are views of the screen only; exports, runs and the magic wand read the picture underneath.
The Object tool takes a box now. Drag one and it selects the object inside; Shift adds, Alt subtracts, Shift+Alt keeps only the overlap. Shift+Alt intersects with every selection tool from now on, and every tool combines softly: a feathered edge stays feathered when you add to it or cut from it, on both the canvas and the tile backend, byte for byte the same. A click or a box on a very large picture no longer builds a full-size mask in memory on the way.
For agents there are three new commands, depth_map, sample_depth and select_range, and set_filter takes a limit; the manual's command list has the details.
Honest notes. The depth model has run on my machine, on a handful of my pictures, and that is the extent of it; if a map looks wrong on yours, I would like to see the picture. This version went through a proper review before it went out, which found a dozen things, among them a multiply layer that darkened the picture where its limit was zero, a magic wand that read the mask view instead of the picture, and a range bar whose edges could not be grabbed while the feather was zero. All fixed, each with a test now. Linux is still built by CI and never run by me.
· v0.1.43
Nano Banana 2.1, a tidier Settings dialog and a long list of fixes
Google's new image model Nano Banana 2.1 arrives on Google's own API and on seven other hosts, with a Thinking setting and the very wide and tall formats. Settings got collapsible groups, a background removal no longer keeps 24 GB of memory, and a handful of things that were simply wrong are right now.
Release on GitHub ↗Google released Nano Banana 2.1 the day before I started on this version, so it is the headline. It has its own recipe, and the default route is Google's own API with a key from Google AI Studio: 1K, 2K and 4K, up to fourteen pictures in one request, and besides the usual formats the very wide and tall ones, 4:1, 1:4, 8:1 and 1:8. New is a Thinking setting with three levels, minimal, medium and high. The model always thinks a little and you pay for it at every level; medium is Google's default and mine too. The same recipe runs on fal.ai, Replicate, WaveSpeedAI, OpenRouter, Comfy Cloud, Comfy Router and ToAPIs, and where the host offers the Thinking setting you get it there as well.
Reading Google's docs for 2.1 turned up three things in the older recipes. A thinking model can send draft pictures before its answer, and the Gemini route used to take the first picture it found, so it now takes the last one that is not a draft. Nano Banana 2's smallest size went out as 0.5K, but Google spells it 512, without the K. And Nano Banana Pro on fal offered 0.5K, which fal doesn't take for that model. All three are fixed.
The Settings dialog had grown to sixty recipe rows and sixteen key rows in one long scroll. The recipes now sit in three groups you open and close, ComfyUI, Comfy Cloud and API models, the last sorted by model family. Each group's line says how many recipes it holds, how many are ready to run and which one is in use, and the dialog remembers what you opened. The API keys are one such group, open while no key is stored. And Remove only shows on your own recipes, instead of sixty greyed-out buttons.
The fix I'm happiest about is a quiet one. After an in-app background removal, Scumble's main process held about 24 GB of memory and kept it until you quit. I measured it model by model: DirectML holds that much after one run of BiRefNet, the processor with its default memory pool still 18 GB, and the processor without the pool 0.4 GB, at nearly the same speed on my machine, about five seconds a cutout. So background removal now runs on the processor, and the memory goes back. If you pick the GPU under Settings, Helpers, it still gets the GPU and gives the memory back after each run, which means loading the model each time.
The rest is a list of things that were simply wrong. After a Generate new whose answer came back at another size than the canvas, as FLUX 3 does at 4K, the boxes stayed at their old pixel positions; they follow the picture now. The Film looks panel showed one long column and, with a black-and-white look active, every thumbnail in grey; it is a grid again and previews each stock over the picture below the look. The ComfyUI window cut a recipe name at its slash, opened a saved graph as Unsaved Workflow (2) and laid recipes out in one tall column; it now shows the whole name and lays the graph out left to right. The assistant's privacy note for a provider goes away after your first message, as it should have from the start, and a key OpenRouter no longer knows says so in plain words. Agents got two fixes: a successful in-app cutout no longer reports itself as a failure, and filter settings sent as text are accepted. When the Inpaint Canvas node pack is missing, the message now gives the git clone line, since the Manager can't install it at the moment.
And a small thing for the project: the Help menu and Settings, About have Star on GitHub and Share the project. Share copies the link or opens the share page of X, LinkedIn, Bluesky or Reddit, with nothing added to track you. After an update, the first start of a new version shows one quiet line asking for a star, once per version, and the little x closes it. A fresh install doesn't show it.
Honest notes. Nano Banana 2.1 is built from the providers' docs and has not run against a live API yet, on any of the eight hosts; if it refuses something, tell me. Two open details are only settled by a real run: whether Google wants the v1 address for 2.1, and how it spells the thinking level. The memory numbers are from my machine with an RTX 5090. And the new ComfyUI window layout was checked against a stand-in page, not yet in a real ComfyUI.
· v0.1.42
A Realism Pass, RTX upscaling and a portable zip
Generated skin that looks like wax gets a fix that runs on your own ComfyUI: the Realism Pass sends the whole picture through DLSS 5 Neural Rendering and lays the answer over it as a layer. NVIDIA's RTX Video Super Resolution joins the upscalers, on your ComfyUI and on Comfy Cloud, and Scumble now also comes as a zip that keeps everything next to it.
Release on GitHub ↗You know the look: a generated face whose skin is too smooth, hair that seems moulded, fabric without a weave. A community node pack for ComfyUI, ComfyUI-DLSS5-Enhancer, runs DLSS 5 Neural Rendering on single pictures, and on the pictures I tried it takes exactly that waxiness away. So Scumble now has a Realism Pass (Windows only, RTX only). The name says what it needs: a ComfyUI on Windows with an RTX 30, 40 or 50 card, plus the pack and its runtime, which you install there yourself. Scumble ships none of it, and there is no Comfy Cloud version, because the runtime has to sit on the machine with the graphics card. The manual has a chapter with the install steps, including the workaround for the runtime installer's download address and the antivirus exclusion the pack's README asks for.
In the app it lives in the Upscale dialog, and in the Image menu. It works like a refiner, not like an inpaint: the whole visible picture goes out at its own size and comes back as a new layer on top, so your picture underneath stays as it was. The layer's opacity is how much of the pass you keep, its Match slider takes back the small colour shift the pass brings, and a mask keeps it off a background that should stay soft. Film looks and grain at the top of the stack stay above the new layer and are not sent, because the pass would smooth grain away as noise. A second run stacks on the first. There is also a recipe of the same name that runs it on a selection, but a passed box can stand out against the unpassed picture around it, so I would pass the whole picture and mask instead.
The pass also upscales: 1.5, 1.7, 2 or 3 times, with the document resized and the passed picture as a layer on top, in one undo step. Testing that on my own pictures found something nobody had written down: above about 30 megapixels of output, DLSS sometimes hands back a picture with broken colours, without any error. 7040 by 4320 came back clean, 7680 by 4320 did not, and right at the border it failed one run in seven. So Scumble stays below 27.9 megapixels and scales a picture down first when the answer would pass that, and it says so in the status line.
Next to it, NVIDIA's RTX Video Super Resolution is a new upscaler: on your own ComfyUI with Comfy's RTX node pack, or on Comfy Cloud on your Comfy key with nothing to install. One to four times, with a Quality setting, fast, and it cleans compression artefacts and edges without inventing detail. The upscalers on your own ComfyUI now also enlarge the whole picture, not only a selection: the answer becomes the new picture and every layer, mask and the selection scale along, as with the API upscalers. A cut-out picture comes back opaque on that route, because ComfyUI loads it without its transparency, and the dialog says so.
Scumble also comes as a portable zip now. Unpack it, and it keeps its settings, keys, autosave and models in a data folder right next to the program, not in your user profile; it runs beside an installed Scumble and doesn't install updates by itself, it tells you when a new version is out and opens its page. Your API keys are encrypted for the Windows account that stored them, so on another PC you type them again.
For agents and the assistant there are twelve new commands: transforming a layer by any angle or into a perspective, cancelling a run, copying the selection to a new layer or another tab, resizing the picture, a screenshot of a region, the base or a mask, selecting by colour and by shape, listing a recipe's settings and applying its presets, and list_recipes now says for every recipe whether it can run right now and why not. Six small bugs from my list are gone too, from flip_layer's axes to the key of a local language model endpoint, which now only goes to the address you saved.
Honest notes. I ran the Realism Pass on my RTX 5090: a 5456 by 3072 picture in about 8 seconds, a box, a transparent picture, and the upscale factors, which is how the colour problem turned up. RTX Video Super Resolution ran on my ComfyUI and once on Comfy Cloud, about 21 seconds for 1024 to 2048 pixels there. Not tried yet: the portable zip started on a second PC, and its full start test on my own machine, which needs my installed Scumble closed; the folder detection itself was checked on the packaged program. The Linux builds are still untried by me. And the 27.9 megapixel limit was measured on one card with one runtime version; if your card does better or worse, tell me.
· v0.1.41
ComfyUI inside Scumble, and recipes for Comfy Cloud
Your own ComfyUI now opens in a window of its own, with the selected recipe as its graph, and what you change there saves back as a recipe. The same window shows Comfy Cloud, and thirteen of Comfy's templates come along as recipes that render there, for edits and for new pictures.
Release on GitHub ↗Every local recipe in Scumble is a ComfyUI workflow underneath. Until now you couldn't see it, let alone change it, without leaving Scumble, opening ComfyUI in a browser and exporting a file. That bothered me since the first recipe. So there is a ComfyUI button in the top bar now (Ctrl+Shift+K, also in the View menu). It opens your ComfyUI's own page in a window of its own: the one on your machine, a box in your network or a RunPod pod, with the address and the login from Settings › ComfyUI. ComfyUI's own shortcuts work in there, and Scumble's never fire from it. The page runs apart from the editor: it can't reach your keys, your files or your documents. And nothing connects anywhere until you open the window; Scumble still needs no ComfyUI for anything else.
The part I wanted most is Edit in ComfyUI, right next to the recipe picker. It opens the selected recipe in that window as its graph, with the result and the Settings rows wired to the Inpaint Canvas node the way a run uses them. Move a node, swap a model, add a LoRA, then Save to recipe in the window's bar writes it back, and the editor selects it. A shipped recipe becomes your own copy under the same name; remove the copy under Settings › Recipes and the original is back. Save as new recipe keeps it under a name you type. The recipe keeps ComfyUI's layout, so it opens next time the way you left it.
The same window shows Comfy Cloud too: a Show picker in the bar switches between your ComfyUI and Comfy's hosted one, and you sign in on Comfy Cloud's own page. Comfy Cloud runs no custom nodes, so the Inpaint Canvas node isn't there, and a recipe built on it can't run on Comfy Cloud. That's why Scumble now has a second kind of recipe: a Comfy Cloud recipe is a graph without the node. Scumble crops and stitches by itself, as it does for every API provider, and hands the crop, the Original, your reference layers, the prompt and the seed to the graph through ComfyUI's own nodes. You get one from a ComfyUI recipe with Cloud copy, by importing a workflow exported from Comfy Cloud, or by saving a graph from the window. Edit in ComfyUI opens each kind where it can run, whatever the window showed last.
Comfy's own templates work as they are. Scumble reads which picture is the crop, where the prompt, the negative and the seed go and which node gives the result, and the window's bar says what it read. No renaming of nodes, unless the reading goes wrong; then a title like Scumble prompt corrects it. That reading had to learn a few things on the way: prompts that pass through a switch or a prompt enhancer, negative prompts hidden in the encoder itself, newer subgraphs, and widgets with sub-options like an image format and its bit depth, which Comfy Cloud refuses when one is missing.
To use them there's a third mode next to local and api: comfy cloud. Pick it and the recipe picker lists your Comfy Cloud recipes alone. Thirteen come with Scumble, picked from Comfy's templates. For edits: Boogu Image 0.1 Edit, Flux.2 Klein 9B base with one or two pictures, Flux.2 dev, Mage Flow Edit Turbo, Qwen Image 2.1 Edit and Qwen Image Edit 2509. For new pictures, through the Comfy Cloud choice in the Generate new dialog: Anima base and preview, Flux.2 Klein 9B, Ideogram 4, Krea 2 Turbo, Mage Flow, Qwen Image 2.1 and Z-Image Turbo, at 768 to 2048 pixels on the long side. Leave the negative prompt empty and the template keeps its own. They run on your Comfy Cloud key, which needs a paid Comfy Cloud plan.
One more thing that was overdue: API runs can be cancelled. While a run waits on a provider, a Cancel button sits next to the timer in the title row. Pressed early, nothing is sent at all; pressed later, Scumble stops waiting right away. The provider may still finish a job it already has, and charge for it. And a bit of tidying: a recipe without Settings rows now says so instead of explaining how to wire the ComfyUI node, and the Sample plugin no longer puts its panel into every tab. Its colour probe, its Posterize filter and the colour-reading command the assistant uses all stay.
Honest notes. I tried the important paths live before the release: Qwen Image 2.1 Edit on Comfy Cloud turned a dog into a cat in about a minute and a half, a Generate new run on Comfy Cloud came back, and a recipe went into ComfyUI and back as my own copy. Testing it found two bugs. The serious one was on Comfy's side of things: Comfy Cloud stopped answering the address Scumble fetched results from, which is what 0.1.40 fixed earlier tonight. The other was mine: Edit in ComfyUI opened a local recipe on Comfy Cloud when the window had shown Comfy Cloud last. Not tried: a RunPod pod in the window, each of the thirteen recipes one by one, and signing in to Comfy Cloud with Google, which may refuse an app window. If something there doesn't work for you, open an issue with what the window's bar or the status line said.
· v0.1.40
A fix for Comfy Cloud
Comfy Cloud stopped answering the address Scumble fetched finished pictures from, so every run there was billed and came back empty. This small release reads the result from the right place again.
Release on GitHub ↗This one is short and a little embarrassing. Comfy Cloud no longer answers the address Scumble used to fetch a finished picture from. The job itself ran fine on Comfy's side, used its credits and made its picture, and then Scumble asked for the result at the old address and got This endpoint is not available on Comfy Cloud back. Every run through Comfy Cloud ended that way: the partner models and the upscalers alike.
I found it while testing the next update, which brings a lot more Comfy Cloud into Scumble. My first two test runs went through, cost credits and showed nothing. Comfy's documentation names the new place: the job's own details, which hold its pictures and, when a job fails, which node failed and why. Scumble reads both from there now, and it asks a few more times when a job has just finished but doesn't list its pictures yet.
If you ran something on Comfy Cloud with 0.1.39 or earlier and got that message, the picture wasn't lost on Comfy's side: the job ran, and its output should be in your Comfy Cloud account. Sorry for the credits.
Honest notes. After the fix, a Comfy Cloud edit came back as it should in my development build, with the next update's code around it; the partner models and upscalers in this release fetch their result through the same code. Nothing else changed in 0.1.40. The bigger Comfy Cloud update comes next.
· v0.1.39
Boxes for Ideogram 4, and FLUX 3 on three more hosts
The boxes from 0.1.37 now go to Ideogram 4 on fal too, as Ideogram's own structured caption, tried live before the release. And FLUX 3 Image runs through fal.ai, Oxen.ai and WaveSpeedAI, built from their documentation.
Release on GitHub ↗Two releases ago Scumble learned to draw boxes for FLUX 3: where a thing goes, what stays, what moves. Ideogram 4 can take boxes as well, but it reads them differently. It doesn't want a prompt with rows of numbers at the end; it wants a structured caption, a short description of the whole picture and a list of the things in it, each with its place. So that's what Scumble writes for it now. Your prompt becomes the description, every New box becomes an object where the box is, every Text box the words it should render, and on an edit every Keep box an element that stays as it is.
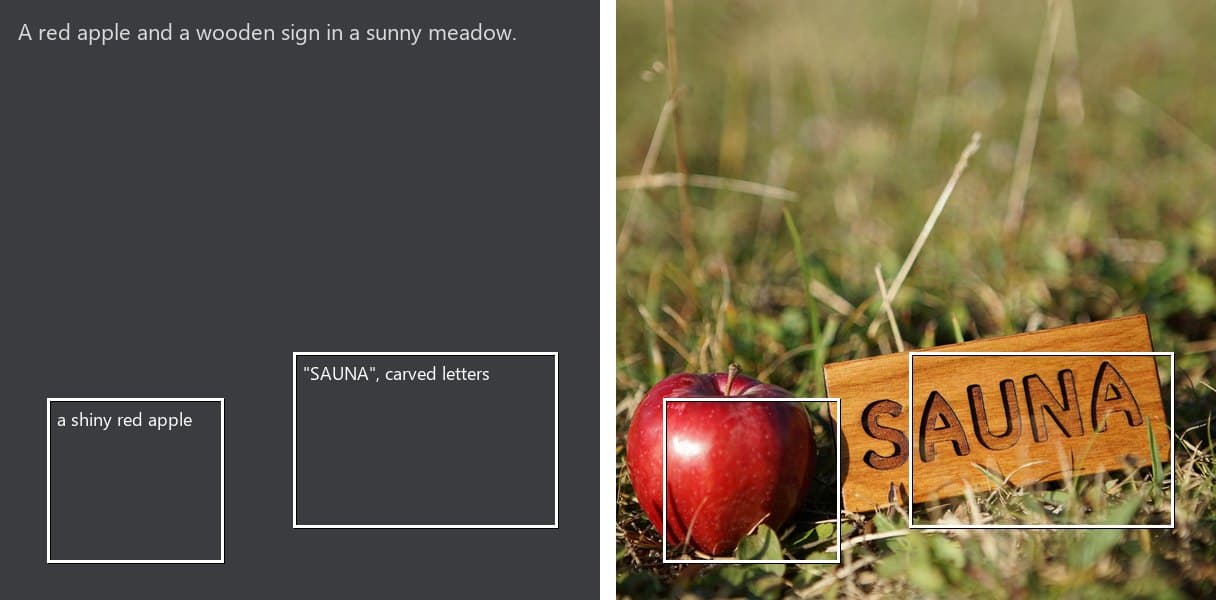
Not every kind of box fits a caption that describes a finished picture. Move, Remove and From reference boxes have no place in it, so they stay out of an Ideogram run, and the Boxes section and the status line tell you which ones were left out. While the boxes go, Prompt expansion goes as None, because an expansion would rewrite the caption and the places with it.
This time I checked the risky part before building the rest: does fal hand such a caption to the model as it is, or does the model end up painting the JSON as text? It hands it over, and the model follows it without rendering any of it. An edit with one box put a black cat into the grass of my selection. A new picture of a meadow with two boxes put a red apple and a carved SAUNA sign where their boxes were; that's the picture below, the two boxes on the left and the answer on the right with the boxes drawn over it. They land roughly, not to the pixel, the sign grew a bit past its box to the left. One surprise on the way: with nothing said about the background, the model painted a transparency checkerboard around the boxes, real grey and white pixels. So on a new picture your prompt also describes the background, and Scumble says so when the prompt is empty. Ideogram 4's recipe also stops calling itself untried on fal, since it has run there now.
The other half is FLUX 3 Image on three more hosts: fal.ai, Oxen.ai and WaveSpeedAI, each on its own key. All three do what Black Forest Labs' own API does: an edit of your crop with up to nine more pictures, a new picture with up to ten references, and the boxes. They differ in the details. fal and WaveSpeed take at most 4 megapixels per picture and fourteen shapes instead of fifteen, without the tallest, so Scumble holds the crop to that size, scales a larger reference layer down and picks the shape among those fourteen. Both have a Prompt expansion switch, which I turned on by default because BFL's own API always expands your prompt. Neither can do grounding, and WaveSpeed has no safety setting either; when the crop fits none of its shapes, WaveSpeed's answer simply follows the crop.
Oxen is the closest to BFL's own API: all fifteen shapes, a Safety tolerance row and a Grounding switch. Oxen's own default for grounding is off; Scumble's row is on, as it is on BFL. Keep in mind that Oxen saves every picture it makes in your Oxen account. The list prices at 1k, as of today: fal 2.4 cents until October 8 and 4.8 after that, WaveSpeed 5 cents, Oxen a little over 6. One thing changed for every Oxen model on the way: a model that takes no seed no longer reports the editor's seed as if it had been used.
A small story from the build: WaveSpeed renamed its FLUX 3 edit route between my research and the build, a day apart. The old name now answers Model not found, so the recipe uses the new one. That's the kind of thing a live run would have caught, which brings me to the honest notes.
Honest notes. The Ideogram boxes ran live as described. FLUX 3 on fal, Oxen and WaveSpeed is written from the providers' documentation and the request schemas they publish; every request Scumble builds is checked against those schemas in the tests, but none of the three has run against the live service yet. If one of them refuses a run, open an issue with what the status line said, and I'll fix it.
· v0.1.38
An update that asks, and FLUX 3 on two more hosts
Scumble now asks when a new version is ready, with a Skip that really skips. FLUX 3 Image runs through OpenRouter and Comfy Router too, tried live on both before the release. Plus boxes in their own colours and a double-click that describes them.
Release on GitHub ↗Until now an update was easy to miss. Scumble checked GitHub a few seconds after the start, downloaded a new version in the background and then showed a small Update to button in the title row, and that was all. I missed it myself more than once. From this version on, once the download is done, Scumble asks: Restart and update, Later, or Skip this version. The question lists what changed since the version you have, one line per change, so you can decide whether it's worth a restart right now.
It tries not to get in the way. It comes once per start and waits while you're drawing, typing or answering another question, the assistant's included, and a key you were typing when it opens answers Later rather than something you didn't mean. Restart and update saves your documents and opens them again in the new version. If a restart would end something in progress, a run on an API or on your ComfyUI, the assistant's turn or an agent's session, it asks first, and the button in the title row does the same now. The Microsoft Store copy never asks, because the Store updates it. Speaking of the Store: the Scumble page here now links that copy, which Microsoft signs, next to the download from GitHub.
One thing I found while building it: the updater installs a downloaded update whenever you close the app, without asking. That's handy for Later, but it would have made Skip a lie, because closing Scumble would have installed the very version you just skipped. So Skip now really skips: closing installs nothing until a newer version comes, and the title-row button and Settings › Updates still install it if you change your mind. Settings › Updates also shows the whole release notes of every version since yours; they used to stop after 4,000 characters, and the notes of 0.1.37 alone were twice that long.
The other big part is FLUX 3 Image on two more providers. The recipe from 0.1.36 now also runs through OpenRouter, on its own key, and through Comfy Router, on the Comfy key you may already have for Comfy Cloud, billed in Comfy credits. Both take what Black Forest Labs' own API takes: an edit of your crop with up to nine more pictures, a new picture with up to ten references, and the boxes from the last release. On OpenRouter the prompt goes exactly as you wrote it and the crop gets the same shape and size class as on BFL; the safety tolerance row works there, but grounding can't be switched, so it stays at BFL's default, on.
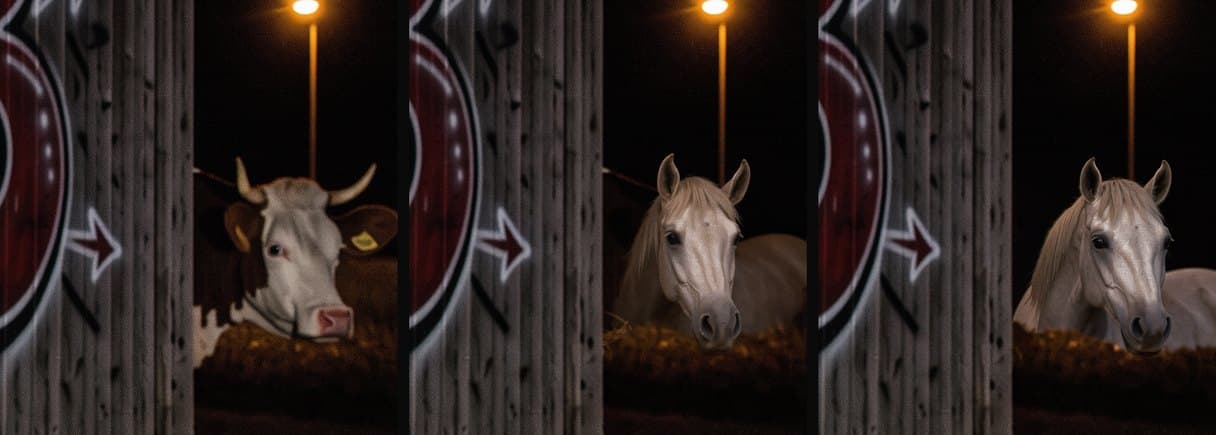
This time I tried both live before the release, with the same two edits on each: a cow looking out of a stall turned into a white horse, and a black cat added to dark grass with my selection sent as a box. The picture below is the horse, the original on the left, OpenRouter in the middle, Comfy Router on the right. Both put the horse where the cow was, and both cats sat in their box. A run took between 40 seconds and almost two minutes. OpenRouter charged 5 cents per edit at 2K; Comfy didn't report what it took in credits.
The test also caught a small fib. When an agent ran generate on an API, the answer said the run took half a second, because the clock only started once the result was already in. It counts from the start now. Agents get the truth about the seed too: generate reports the seed the model actually got, and on a route that sends none, like FLUX 3, it says so, and the result's row in the history says no seed sent instead of offering one that was never used.
And the boxes got friendlier. Every new box takes its own colour, so six boxes are six colours instead of six greens, and the kind shows in the shape: a dashed source and an arrow for Move, hatching for Remove, a T for Text. Double-click a box with the Boxes tool and you can write its description right on the picture. Boxes are named after the thing, not its adjectives: a small black cat sitting in the grass is black_cat_1 now, where it used to be small_black_1, and that works in German too. And a crop widened to one of FLUX 3's shapes always asks for that shape now; a rounding slip of more than 3 percent used to send it as auto.
Honest notes. FLUX 3 on OpenRouter and Comfy Router ran live as described, two edits on each. Comfy doesn't publish a price for the model and didn't report one per run, so have a look at your credits after the first. And the update question lives in the version that gets updated, so 0.1.38 is the first one that asks: updating to it from 0.1.37 still works the old, quiet way, and you'll see the question when the next version comes out. If it asks at a bad moment, open an issue and tell me when.
· v0.1.37
Boxes: telling FLUX 3 where things go
FLUX 3 Image reads boxes in the prompt, and Scumble now draws them: your selection as one box, or boxes of your own on the picture to add, keep, move or remove things and to place a reference. Tried live before the release. Plus Ideogram 4.5 on three providers.
Release on GitHub ↗In the last post I wrote that FLUX 3 can take bounding boxes in the prompt, and that turning a selection into one was the obvious next step. That's this release, and it grew on the way: Scumble now has a small box editor for it.
The simplest part is one switch. Under the prompt field there's a row called Boxes, shown while the recipe takes them, which for now means FLUX 3 Image. Turn it on and, with no boxes drawn, Generate sends your selection as one box: the model is told where in the crop the change goes and that your prompt says what goes there. If your prompt names a reference with @img1, the box says that this reference goes there. Switched off, a run goes out exactly as in 0.1.36. The switch is saved with the document, and the first box you draw turns it on.
Then the editor. A new Boxes section in the Generate pane keeps the document's boxes, and the Boxes tool (X) draws them on the picture: drag for a new one, click to select, drag to move, pull a handle to resize, Delete, D to duplicate, the arrow keys to nudge. Every box has a kind. New puts in what its description says, Keep holds something where it is, Move takes it from a source box to a new place, Remove takes it out, From reference places a reference layer or a part of it, and Text renders words. They show on the picture in their kind's colour, they're saved in the .scumble file, they follow a crop, a turn or a resize of the picture, and every change is one undo step.
What goes out is what Black Forest Labs documents: rows with each box on a grid of 0 to 1000, after your prompt. Scumble adds a sentence per box in plain words, like place a red scarf at the top left, or move the lamp up and to the left, larger, because the model reads words more reliably than numbers. Your own prompt goes first, untouched. Boxes take their names from their descriptions, and the section warns before you pay for a run that would go wrong: a box the crop leaves out or cuts, a box too small for the model to put anything in, a new box without a description, or a box that changes the picture outside your selection while Paste keeps only the selection. While the tool is active, the part of the picture Generate won't send is dimmed, so you see the crop before it goes.
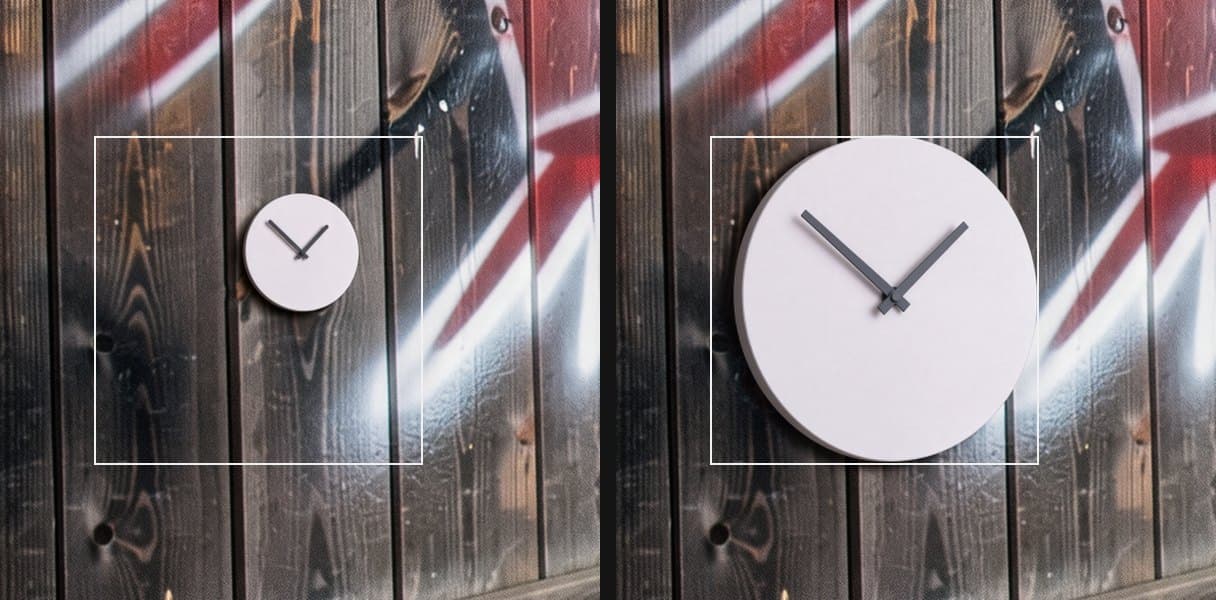
This time I tried it live before the release: five edits at 1k, 5 credits each. Asked to add a small black cat to the grass, FLUX 3 without a box put the cat at the edge of my selection, half across it, where Scumble's paste would have cut it in two. With the selection as a box, the cat sat right in the middle. Asked to hang the clock from a reference picture on a wooden wall, it took the right clock both times, but with a From reference box the clock filled the box exactly; that's the picture below, without the box on the left and with it on the right, the box drawn in white. And a Remove box took out a street lamp together with its glow and left the cow next to it alone. One thing I learned: the model takes a box's size seriously. My small cat came back as large as the box, so draw a box at the size the thing should have.
Agents get all of it: boxes_add, boxes_set, boxes_remove, boxes_list, boxes_from_selection and boxes_clear, plus the switch through set_generation. The assistant adds and changes boxes by itself and asks before it removes any. Because the box editor is a built-in plugin, other plugins can supply boxes too: plugin API 3 has scumble.generate.register, and Scumble maps whatever a plugin answers into the crop and writes the rows. The release tests caught one thing on the way out: the new commands had reached the assistant without a rule for what it may do with them, and the assistant's test refuses that. Fixed before the release.
The other new model is Ideogram 4.5, a recipe on your Replicate token, your WaveSpeed key or Comfy Router. It's an edit model that takes your selection as a real mask: it changes what's selected and leaves the rest of the crop exactly as it was, pixel for pixel, and it's good with lettering. Up to three more pictures go along, the Original and your reference layers, but Ideogram takes them without numbers, so @img1 can't point at one. The Settings panel has Quality, which is also the price: an edit on Replicate or WaveSpeed costs $0.008 at very_low, $0.06 at the default medium and $0.22 at high. Generate new makes a picture from the prompt alone.
Honest notes. The boxes ran live as described; Ideogram 4.5 is built from Replicate's, WaveSpeed's and Comfy Router's documentation and hasn't run against the live services yet, so if it refuses a run, open an issue with what the status line said. Boxes go to FLUX 3 Image on Black Forest Labs for now. Ideogram 4 has a box format of its own, and that may come later.
· v0.1.36
FLUX 3 on day one
Black Forest Labs released FLUX 3 Image today, and Scumble runs it the same evening: edit a selection or make a new picture, with up to ten reference images. Plus questions in Scumble's own dialogs instead of the system's boxes, and three fixes.
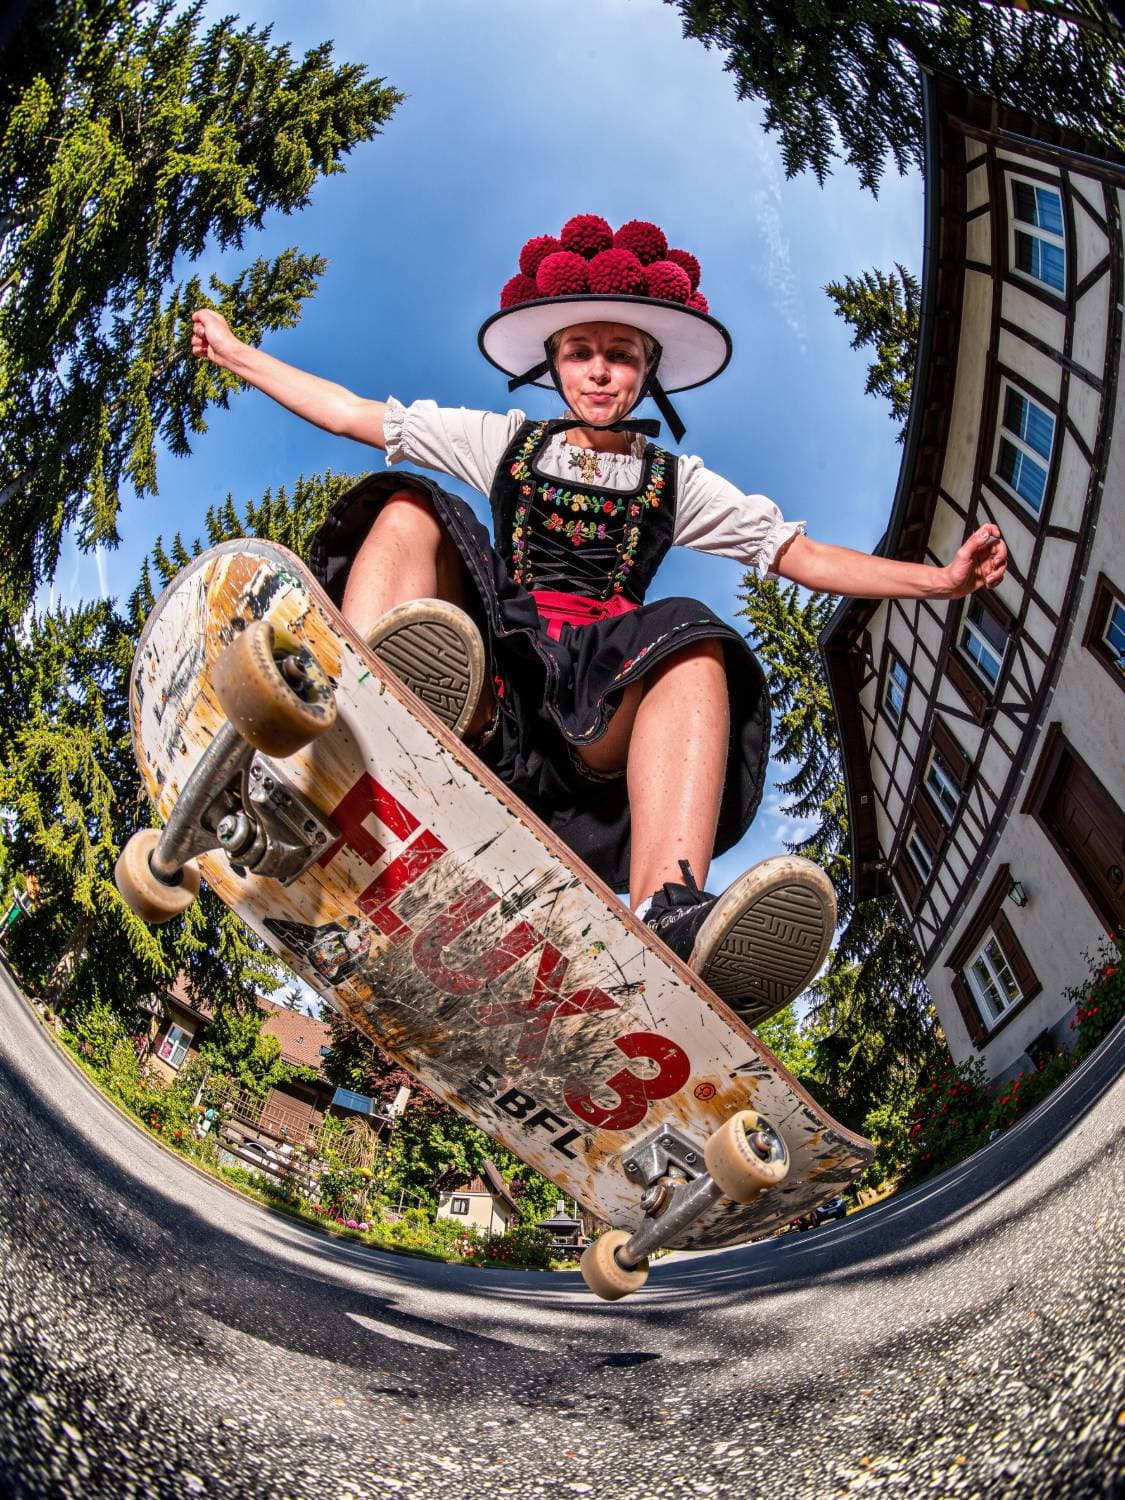
Release on GitHub ↗Black Forest Labs released FLUX 3 Image today, and it's in Scumble the same evening. From my first runs it's a big step: pictures that look photographed rather than generated, detail that holds when you zoom in, long prompts with many people and things in them that come back the way I wrote them, and a model that keeps adding ideas I didn't ask for and that make the picture better. The picture below is my welcome to it, made with FLUX 3: a Black Forest girl, Bollenhut and all, kicking a skateboard into the air.
In Scumble it's a recipe called FLUX 3 Image on your Black Forest Labs key. An edit sends the crop of your selection plus up to nine more pictures, the Original and your reference layers. Generate new makes a picture from the prompt with up to ten reference images. Your @img tokens go out under the names FLUX 3 gives its pictures, image 1, image 2 and so on. On an edit the crop is image 1, so @img1 goes out as image 2; on a new picture it's image 1.
FLUX 3 takes no pixel size. It knows fifteen shapes and three size classes of about 1, 4 and 16 megapixels. Scumble widens the crop to the nearest of the shapes, so the answer fits back onto your selection exactly, and picks the class from the crop's size: with the default crop size an edit goes at 2k, a new picture at whatever you choose, up to 4k. The classes cost differently on BFL's price list, about 5, 10 and 61 cents a picture when I looked, so 4k is something you pick in Generate new, never a surprise.
Two things are new for a Black Forest Labs model. FLUX 3 can search the web and images for what your prompt names before it renders; BFL calls it grounding. It's on by default in their API and in Scumble, and the recipe's Settings panel has a switch if you'd rather your prompt didn't go to a search. And there's no seed: two runs of the same prompt come out different, which is how the model is built. It also expands a short prompt by itself, and Scumble's log keeps that expanded prompt next to what the run cost.
I built it from BFL's documentation the day it came out. Their API is strict, a field it doesn't know is refused, so Scumble sends exactly the six fields it takes and checks every picture before anything leaves your machine: at least 256 pixels a side, at most 16 megapixels, at most 20 MB each. A reference layer outside that is scaled to fit; the crop never is, your selection decides it. While I was in there, every Black Forest Labs run, FLUX.2 included, learned to wait out a busy server or a dropped connection instead of giving up after the job is already paid for.
The other big change is quieter. Scumble's questions used to come in the system's message boxes or the browser's plain box, grey and out of place. Now they open inside the window in the colours of your skin: Save or Don't Save when a tab closes, a file that changed on disk, quitting while the last changes are still being saved, removing a recipe or a helper model. Enter answers the highlighted button, Escape cancels, the arrow keys move between the buttons, and a question that deletes something has Cancel highlighted. A skin can recolour them but can't hide them. Plugins get the same dialog.
Three fixes. Generate new with Nano Banana on a Google key ignored the aspect you asked for when the recipe's Aspect row was on auto, so a 16:9 picture came back square. Switching between the two local ComfyUI recipes kept the other one's model files in the Settings panel, so a run loaded the wrong ones; each recipe keeps its own now. And for agents, --attach-only makes an MCP registration drive a running Scumble and never start one in the background.
Honest notes. The FLUX 3 code was written from the documentation and tested against a scripted stand-in of BFL's API, 96 checks of what goes out and what comes back, and before the release I ran it live from Scumble: an edit of a selection with a reference layer and a new picture with one. Both went through on the first try and the edit sat in its selection without a seam. Expect a run to take one to two minutes; the model thinks before it paints. Peeking at the prompt it expands, it even plans an edit with boxes of its own: what to keep, and where a new thing goes. FLUX 3 can take such bounding boxes from you too, written into the prompt; Scumble doesn't turn a selection into one yet, and that's the obvious next step. If FLUX 3 refuses a run Scumble thinks it takes, or a picture comes back in the wrong shape, open an issue with what the status line said.
· v0.1.35
Many layers, one hand
The layer list grows up: select several layers and move, scale, merge or delete them together, line them up and space them out, clip a layer to the one below, put layers into groups, and add fill layers of one colour or a gradient.
Release on GitHub ↗Last time I wrote that layers came next, and here they are. Until now the layer list did one layer at a time: one to move, one to merge, one to hide. That was fine for an inpaint and a correction on top, but once a picture has a dozen layers it gets slow. This release is five things that make a long list manageable, and I built them in the order you'd miss them.
First, several layers at once. Ctrl+click a row to add it to the selection, Shift+click to take every row in between. With the transform tool the selected layers move together, the handles of the box around them scale them together, and the arrow keys nudge all of them. Ctrl+E merges them into one layer where the topmost was, Delete removes them, and the eye and the lock of a selected row switch all of them. Rotate, distort and warp still take one layer at a time; one pending transform over several layers is a bigger piece of work than it looks.
Hiding everything but one layer existed already, as Alt+click on the eye, but it wasn't in the manual and it forgot things: moving the solo from one layer to the next brought back the first solo instead of the picture you started with. Now the way back always ends where you started, it works on a selection of several layers, and a right click on a row offers it as Show only this layer, next to Show all layers, merge and delete. It also leaves reference layers alone now. A hidden reference isn't sent to the model, and solo used to hide them behind your back.
Second, align and distribute. The transform tool's bar has six buttons that line up the selected layers on an edge or a centre, and two that space them with equal gaps, either inside the box around them or across the whole canvas. They go by each layer's box, the frame the transform tool draws, not by what's painted in it. That's a choice: going by the painted pixels would mean reading every layer's tiles on each click, and a full-canvas paint layer would still not move. Tell me if you want the painted pixels instead.
Third, clipping. Alt+click the line between two rows, press Ctrl+Alt+G or use the row's menu, and the upper layer shows only where the layer below has pixels. It's the quickest way to put a texture on one object, or to grade one object with a filter layer, because a clipped filter layer only changes what lies under the layer it clips to. This one touched every path that draws the picture: the screen, the GPU compositor, the workers that export, the box reads for a run. Where the lower layer is only partly there, at a soft edge or a feathered mask, each clipped layer is drawn over the picture with that partial strength. That means two clipped layers can look a little different there from the same two merged into one. PSD files keep the clip both ways; ORA has no clipping and gets the layers unclipped.
Fourth, groups. Ctrl+G puts the selected layers into a folder with its own row: fold it, hide all its layers with its eye, lock them with its lock, rename it with a double click. A click on the row selects its layers, so they move together. Drag layers in and out, nest groups inside groups, and Ctrl+] and Ctrl+[ step a layer into a group next to it or out of its own. A group has no opacity or blend mode of its own on purpose: its layers are drawn exactly as if it weren't there. A group that blends as one picture means compositing it first and then blending the result, on every path, and I parked that for now. Merging the layers and setting that layer's opacity does the same today. PSD files keep the groups both ways.
Fifth, fill layers. A new button next to the filter button adds a layer of one colour, starting in your paint colour. Its row turns it into a gradient, linear, reflected or radial, from that colour to transparent to start with, and each end gets its own colour and opacity. A fill covers what's below until its blend mode, opacity or mask lets the picture through: a gradient to transparent in multiply darkens one side and leaves the other alone. It stays sharp at any size because it's worked out for each pixel from its place, not stored as pixels. PSD and ORA get it as an ordinary layer of pixels.
Before the release a check of the release notes against the code found three things I fixed. Ungrouping a hidden or locked group showed and unlocked its layers, although the code's own comment said they'd keep that state. Switching a fill to a gradient started from black to white instead of the fill's colour. And the notes said the eye and the lock of a selection were undo steps, which they aren't, as they never were for one layer.
Honest notes. The multi-selection, align and the fills went through one test each and a look in the app; the clip and the groups, which decide what the picture looks like and what goes into a file, got the full treatment: every drawing path compared, broken on purpose to see the tests catch it, and measured on a 15k document. What none of it has had yet is your hands on it. How the multi-selection feels, whether the gradient's default is the one you'd want, whether the clip at soft edges looks right: tell me.
· v0.1.34
Say which picture
Reference layers get names you can write into the prompt, @img1 and @img2, and Scumble writes each one the way the chosen model knows that picture. They show as chips with their picture, stay with their layer when you reorder or hide, and Generate new sends them along now too.
Release on GitHub ↗Last time I wrote that naming reference pictures right in the prompt came next. Here it is, and it's the biggest change to the prompt field since the beginning. Reference layers have been in Scumble for a while: the pictures in the reference list go to the model along with the crop, so it can take a colour, a pattern or an object from them. What was missing was a way to say which is which. Now you write @img1. In the picture below the prompt reads “the handbag covered in the purple glitter of @img1, with a small enamel pin of @img2 on its flap”, every token shows as a chip with its picture, and resting the mouse on one brings up a card with the layer's name and what the model will get it as.
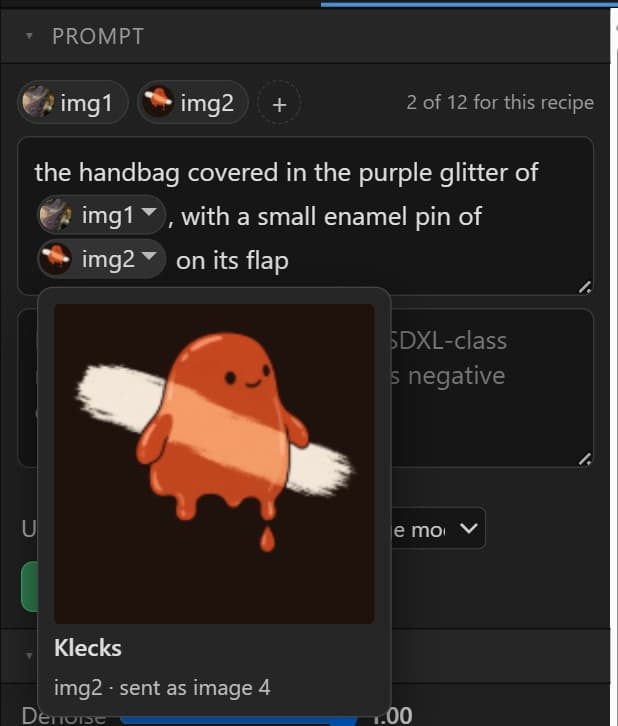
Why not just write “the second picture”? Because every model counts its pictures its own way, and you'd have to do the counting. On an inpaint run the crop goes first, and with Original on, the crop as it was before the fill goes second, so your first reference is image 3. Some routes send the mask as a picture of its own too. A local Qwen Image Edit 2.1 graph reads <image3>, FLUX.2 Klein reads image 3, and Nano Banana on Gemini gets a label in front of each picture when it gets several. The old numbers in the reference list didn't help either: they said ref 1 and ref 2, not what the model saw, and a new reference jumped to the top and renumbered all the others. Now you write @img1, and at the moment you click Generate, Scumble writes whatever the chosen model and route read for that picture. Your prompt keeps the token, and the status line says what each one went out as: “Named in the prompt: @img2 → image 3.”
A token stays with its picture, and that took more thought than the chips did. The labels count the shown references from the top of the list, img1, img2 and so on, and a new reference now goes below the others and takes the next number, so adding one renumbers nothing. Move references around, hide one, show it again, merge or delete, and the tokens in your prompt are rewritten so each still names the same layer. Hiding does renumber, because a hidden reference isn't sent: hide img1 and the old img2 becomes img1, and its token in the prompt follows. The hidden one's token waits, struck through, and Generate stops and says why until you show the layer again or take the token out. A deleted one's token waits the same way until you undo the delete.
The prompt field had to become something new for this. A plain text box can't hold a picture, so the field is now a small editor of its own. A chip counts as one character: the caret steps over it and Backspace takes it whole. A token turns into a chip once you type the space after it, so you can type @img12 without passing through a chip for @img1 on the way. The field has its own undo too: Ctrl+Z there takes back typing, a paste, an Upsample or a prompt an agent set, never an edit of the picture.
Type @ and a list of the shown references opens under the caret, each with its picture, its layer's name and what the model gets it as. Keep typing to narrow it, Enter or Tab puts one in. At the end of the list, + Add reference loads pictures as new reference layers and names them right where you are, and a picture pasted or dropped onto the prompt does the same. One small trap on the way: when the list opened right under a resting mouse, the browser reported a mouse move of no distance, the row under the pointer took the highlight, and Enter put in that one instead of the first. Now a row follows the mouse only when the mouse actually moves. Above the field a bar shows every reference as a chip, a + to add more, and how many the recipe takes, and a chip past that limit gets a yellow edge. The small arrow on a chip swaps it for another reference, and a chip can be dragged to another place in the sentence.
Generate new takes references now. It used to start over from the prompt alone and throw away every layer, references included. Now the new picture replaces the old one and every other layer, but the reference layers stay, and the shown ones go to the models that take reference pictures for a new image: FLUX.2, GPT Image, Nano Banana, Seedream and HY Image 3.5, Qwen Image Edit on most of its routes, and Grok Imagine on fal, OpenRouter and Oxen.ai. On those routes there's no crop in front of them, so @img1 is image 1. A local recipe renders onto a white canvas that goes first, so there @img1 is the second picture, or the third with Original on, and the dialog's chips show which. A model that works from the prompt alone keeps them in the tab and stops the run if the prompt names one, rather than sending a sentence about a picture it never gets. The dialog has the same prompt field, with the chips, the list and the bar. And you can start from nothing: in an empty tab, a reference added through the prompt field gets a white 1024 by 1024 canvas for Generate new to replace.
Upsampling knows about the tokens. The language model is told which reference each token names and to leave the tokens alone, and Scumble checks what comes back: if the rewrite dropped a token, added one, or wrote image 3 instead, the status line tells you, and Revert gives you your own prompt back. With an API model or a local one behind an OpenAI-compatible server, the language model also sees the pictures the prompt names, up to six and at most 512 pixels each, so it can write about what's actually in them. That means those pictures go to that model's provider along with the crop. It's on by default, and the switch that keeps them back is in Settings, Prompt templates. On the local endpoint, ToAPIs, OpenRouter and Oxen.ai, a model that turns the pictures down is asked again with the crop alone, and the status line says crop only. And a model marked in Settings as not seeing pictures now really gets none, not even the crop.
The local ComfyUI recipes name the pictures too. On Qwen Image Edit 2.1 a token goes out as <image3>, on FLUX.2 Klein as image 3, the way those graphs number their pictures. Both read more pictures now, Klein up to 4 and Qwen up to 10, the crop and the Original included. While mapping the code for this I found a bug of mine: Klein read the crop and one more picture, so with Original on no reference reached it at all, and nothing said so. Both also filled the slots the batch left empty with copies of the last picture. They don't any more, which means the same seed gives a different result than in 0.1.33. A reference past what a recipe reads is left out with a note, and a token that names it stops the run. A workflow of your own is read the same way, and where Scumble can't tell how its graph numbers the pictures, it writes image 3 by the place in the batch and says the wording is a guess.
No reference goes missing without a word any more. Once I looked, several routes quietly dropped pictures past their limit: FLUX.2 on Black Forest Labs kept seven references and threw the rest away. Now every route does one of three things. It sends every picture. Or it refuses before anything is sent, with the count and what to do, hide a reference or turn Original off. Or, where the endpoint takes no reference pictures at all, like the FLUX.1 Fill endpoints, it sends none and says so, and a prompt that names one stops the run. The limits come from each provider's documentation. Where a route wraps your prompt in a sentence of its own, that sentence now numbers the pictures the way the tokens do.
Smaller things. The up and down arrows in the reference list step past the next reference; with an image layer between two references a click used to add an undo step and change nothing. Changing a layer's role is an undo step of its own. Generate new on Replicate keeps the aspect you ask for with FLUX.2, Nano Banana and Seedream. Agents see each reference's label and what it goes out as, can pin a token to a layer with set_prompt, and generate returns the prompt as it was sent. The manual has a new chapter, Reference images in the prompt.
Honest notes. None of this has run against a live API or a real ComfyUI yet. Every test ran offline: the requests are checked against what each provider's documentation says they should look like and answered by a stand-in, and the two local graphs were checked as the graph Scumble builds, not run. The ComfyUI on my machine is busy with real work, and the Qwen Image Edit 2.1 local recipe has never run here at all, its models aren't downloaded. So the limits, the wording and the numbering are what the documentation promises, not what I've watched a model do. If a model mixes up which picture is which, or a provider refuses a run Scumble thinks it takes, open an issue with the recipe, the provider and what the status line said. And the prompt field is new code under your fingers: if the caret lands somewhere odd or a chip won't go away, tell me that too.
Next up: layers. Selecting several at once and moving them together, aligning and distributing them, clipping a layer to the one below, groups as folders, and fill layers.
· v0.1.33
One move, one stroke
A quick fix for the eraser: since 0.1.32 it got four to five times slower with a big brush under a pen, and so did the brush, clone and heal. Back to 0.1.31's speed, pressure and all.
Release on GitHub ↗A day after 0.1.32 went out, erasing turned out to be really slow: on large pictures it lagged behind the pen and stuttered, and it felt worst inside a selection. That was a regression, and it was mine, so here is a small release that does nothing but fix it.
What happened: a pen reports its position far more often than the screen draws a frame, so the browser hands the editor a small batch of points with every move. For 0.1.32 I started using all of them, so a fast curve stays round and the pressure lands point by point. But each of those points became a little stroke of its own. Every one got its own working area in the stroke buffer, which on a big picture is a copy in and a copy out, its soft dabs were stamped at both ends, so every point in between got two, and clone and heal read the picture again for each. With a 1,000 pixel eraser on a 15,000 by 10,000 picture one move went from about 22 to about 109 milliseconds, well past a frame. And it fed on itself: a slow frame means a bigger batch of points for the next move, which makes that one slower still. The hard brush, clone and heal had the same problem, heal up to seven and a half times slower.
Now a move is one piece of the stroke again. All its points go through in one pass, one working area, the dabs spread evenly along the whole path the pen took, the way one segment was stamped in 0.1.31, and each still at its own pressure. The same 1,000 pixel eraser takes 19 milliseconds a move, a little less than in 0.1.31, the hard brush 10, and clone and heal about a fifth of what they cost in 0.1.32. Inside a selection the numbers are the same. With the mouse nothing changes at all: a test checks that a straight move of eight points erases exactly the bytes that one point erases.
A review of the fix turned up two smaller things from 0.1.32, and they're fixed too. When the pressure rose within a single frame, the big dabs were spaced as closely as the smallest one, which made a soft edge a little harder under a pen than under the mouse. And Follow stroke didn't turn an imported tip at all when the pen moved slowly, because it took the direction from pieces less than a pixel long.
Honest notes. In my measurements a selection costs nothing extra per move, the slowdown was the same inside and outside it. If erasing still feels slower inside a selection for you, tell me what kind of selection it was and how far you were zoomed in. Clone and heal with the very largest brushes are still a little slower than in 0.1.31. That's the price of reading only what's under the brush, which saves half a second and up to 1.7 GB at every press. And the smudge still takes each pen point on its own. It's nowhere near as slow as the 0.1.31 smudge was, but changing it changes how a pen smudge looks, so I want to try that by hand first.
Next up: naming reference pictures right in the prompt, @img1. That's 0.1.34. Then layers.
· v0.1.32
Brush it away
Brush over something and it's gone: Remove runs LaMa inside Scumble, Patch and a content-aware move repair and rearrange, and the healing brush finally blends without a rim. Plus Liquify, straightening, and a whole round of brush work.
Release on GitHub ↗Last time I wrote that straightening and the brushes came next. Both are in, and so is the part of the long list I'd been looking forward to most: taking things out of a picture without writing a prompt or sending it anywhere. Three pieces of that list landed at once, so this is a long one.
Remove is a new tool, Shift+J, right beside heal. Brush over whatever should go, a person in the background, a wire across the sky, a spot on the lens, let go, and LaMa fills the stroke from what's around it. LaMa is an inpainting model built for exactly this job, and it runs inside Scumble: no prompt, no key, no ComfyUI, no internet once you have it. You download it once in Settings, Helpers. The tool loads it when you pick it, about ten seconds the first time, and after that a stroke takes a second or two. The fill goes into the active layer as one undo step, or into a new layer when you're on the base, so the original stays untouched underneath. The same model is a recipe too, LaMa remove (in-app): select, pick it, press Generate.
I wanted it on the graphics card. It wouldn't go: DirectML stops at the first run of this model whatever I set, so it runs on the processor. And because the library that runs it holds whatever thread calls it for the whole run, it lives in a process of its own. My first version used a worker thread, and a review found that stopping it in the middle of a run, say when you quit, took the whole app down with it. A separate process can simply be ended where it stands, and while LaMa thinks, the window, the agents and the autosave keep going.
The healing brush finally does what its name promises. Heal (J) used to copy the source and nudge its colour towards the place it landed, which often left a faint rim. Now, when you let go, it lays the source's texture into the colour and light around the stroke, right up to its edge. That's a gradient-domain blend, Poisson if you know the word, and it's how Photoshop's healing brush works too. While you paint you still see the quick version. A spot heals at once, a large stroke takes a moment and the brush waits for it, and a Ctrl+Z pressed in between takes it back as soon as it has landed. The solver is new and written in Rust: a 512 pixel patch settles in about 70 milliseconds, a disc 2,000 pixels across in a little over a second.
Two more tools share that solver. Patch (Shift+J a second time) repairs a whole area: lasso the spot, drag the selection to a place where the picture is right, and let go. That texture is laid into the spot and takes on the light around it, again without a rim, and while you drag, the spot already shows what it would take. Destination does it the other way round and copies the selection to where you let go. The selection stays, so a second try is just another drag. Content-aware move (Shift+J a third time) moves something: lasso it with a little of its surroundings, drag, let go. It lands as it was, its edge blending into the new place, and LaMa fills the hole where it stood. Extend leaves the original where it is and places a copy, and that one needs no model at all.
Liquify (Shift+W, or Ctrl+Shift+X like in Photoshop) bends the picture with the brush: push drags it along, grow swells what's under the brush, shrink pinches it, swirl turns it, restore brings it back, and Alt swaps grow and shrink or the swirl's direction. You see the result while you drag, and every stroke is one undo step. The part I spent the most time on is invisible when it works. The easy way to build liquify is to let every stroke resample the result of the one before, and after twenty strokes the face is a little blurry. Here every stroke of a session is taken from the layer as it was when you started, through everything you've pushed so far, so nothing softens, and Restore all gives you the original back to the byte. A selection limits it, and so does a freeze: paint over what must not move, it shows in red, and Alt thaws it again. On the base it works on a copy called Liquify. On a 15,000 by 10,000 picture with a 1,000 pixel brush the preview draws a frame in 14 to 19 milliseconds, and a stroke lands in well under a fifth of a second. There's no OK button: a stroke lands when you let go, and picking another tool ends the session.
Straightening is in. The Canvas tool (C) turns the whole picture by up to 45 degrees either way (the quarter turns in the Image menu do the rest) and crops it in the same step: drag outside the frame to turn it, type the angle, or hold Ctrl and draw a line along a horizon or a wall, and the picture turns until that line is level or plumb. The frame stays inside the turned picture, the largest one of the shape you chose, so there are no empty corners. Every layer, every mask and the selection turn with it, text stays editable, and one Ctrl+Z takes it all back. Last time I said this needed a different approach for pictures bigger than a browser canvas. It's a resampler that works tile by tile, now in Rust, and a 15,000 by 10,000 picture with four full layers straightens in about five seconds with the window staying responsive. The frame also waits for you now: dragging it used to crop or extend the moment you let go, now you move and resize it as often as you like and press Enter, click Apply or double-click inside it when it's right. It has aspect presets (X turns one on its side) and can show thirds, the golden section, a grid or diagonals to compose by.
Then the brushes, which got a whole round of work. The smudge carries paint now: it picks up what it passes and lays it down as it goes, Length says how far it carries, Finger starts every stroke with the paint colour on the brush, and like a real smudge it drags transparency too. Its new Mode turns it into a blur or a sharpen brush. Dodge, burn and sponge are a brush of their own (Shift+O): lighten or darken the shadows, midtones or highlights with GIMP's curves, with Protect tones so colours keep their hue, and a sponge whose Vibrance lifts the dull colours most. For the classic way there's Image, New Dodge & Burn Layer, an empty soft-light layer to paint white and black on.
Around them: Flow, so a stroke builds up where it passes again, a pressure curve for a light or a heavy hand, and a stabiliser that pulls the brush along on a string, so a trembling hand draws a calm line. Clone and heal can turn, scale and mirror their source now and show what they'd copy right under the brush. Brush tips got a picker, every tip drawn as a stroke, grouped by file, with a search for packs of hundreds. And brushes go up to 1,000 pixels. That one needed smudge, clone and heal to stop reading the whole picture: clone and heal flattened all of it at every stroke, up to 1.7 seconds on a 15,000 pixel picture before the brush even moved, and the smudge could take eight seconds a move. Now each reads only what's under the brush, a few milliseconds a move at any picture size (a few tens with the very largest brush).
One for retouchers: Image, Frequency Separation splits the picture, or the selection's box, into a low layer with the colour and tone and a high layer with the texture, which together give the picture back exactly. Even out skin on one, heal pores on the other. The high layer needs the linear light blend mode, so every layer can use that now, and PSD keeps it both ways. A document with a linear light layer needs 0.1.32 to open, everything else still opens in 0.1.31. A few fixes came along too. PNG exports carry the prompt and the recipe again unless you untick it. I had switched that off in 0.1.30 so your prompt wouldn't travel with every picture unasked, but the prompt is the useful part; what must never leave is a key typed into an imported workflow, and anything a recipe names like a key, a token or a password now stays out of the file. One catch: 0.1.30 and 0.1.31 couldn't tell a deliberate untick from their own default, so this update switches it on for everyone. If your PNGs should carry nothing, untick it once more; from now on it stays as you set it. The Opacity slider is back for the brushes, [ and ] size the brush on a German keyboard, text keeps the font file it was set in, and running out of memory now says so instead of leaving a stroke half written.
Honest notes. LaMa sees the world at 512 by 512 pixels. A small spot is filled at full resolution, but for a large stroke the area around it has to be scaled down to that size and the fill back up, so it comes back softer than the picture around it. It's also a 198 MB download, and on the processor it's a second or two a stroke and about ten seconds to load, not instant. A heal where the source's transparency splits into thin strands, a cut-out of hair or a fence, doesn't settle yet and keeps the quick version. And the Liquify preview while you drag is a little softer than the stroke that lands.
Next up: layers. Selecting several at once, aligning and distributing them, and clipping a layer to the one below.
· v0.1.31
Turn it around
The whole picture rotates and flips now, every layer with it. Your undo steps are a list you can click through, masks stay masks on the way to Photoshop and back, and Tab hides everything but the picture.
Release on GitHub ↗Press Tab and everything but the picture goes away: the tabs, the bars, the tools, the side panel, the rulers. The window goes full screen and the picture fills it, and every tool and key keeps working. Tab again or Escape brings it all back, with your zoom and the window as they were. I wanted this for judging a result without a single button in the corner of my eye. It's also in View, Canvas Only, and a Tab typed into a text field is still just a Tab.
The undo history is a list now. A new section in the Image tab names every step, Brush stroke, Rectangle selection, Merge down, Crop canvas, oldest first, and a click jumps to any of them, forward or back. The steps you undid stay listed below until you edit again. Next to it are snapshots: they keep the whole document under a name to come back to later, up to eight per tab. Taking one costs nothing, and going back to one is an undo step of its own. How deep the history goes is a setting now too. On a 15,000 pixel picture a single whole-layer step can hold hundreds of megabytes, so it's worth knowing where that memory goes.
Layer masks used to vanish on the way into a PSD: the export baked every mask into its layer's transparency, and whatever you hid was gone for good in Photoshop. Now the layer's pixels go out whole and the mask goes along as Photoshop's own layer mask, so Photoshop, Affinity, Krita or GIMP can keep editing it. Opening a PSD keeps its masks as masks too. And a mask can be switched off without deleting it, with the eye in the mask row or Shift+click on the word mask, the way Photoshop does it. The switch travels in the PSD in both directions.
The mask row got a small menu, the three dots, or a right click on the word mask: Reveal all, Hide all, Reveal selection, Hide selection, Invert. Hide all and then painting the mask where a result should show is the quickest way I know to take just a part of a generated layer. Each of these is one undo step, and agents can do all of it with a new set_mask command.
The big one: the whole picture rotates by 90 or 180 degrees and flips, from the new Image menu or the Turn row in the Canvas section. Every layer turns with it, and so do the masks, the selection, the guides, saved selections and earlier results in the history. Text stays editable and keeps its turn when you type into it again, 3D objects and film control points follow as well. Nothing gets resampled, so four quarter turns give back exactly the same pixels, and the whole turn is a single Ctrl+Z. On a 15,000 by 10,000 picture with four full layers it takes about three seconds, and in my measurement the window was never stuck for more than a quarter of a second of that. I rewrote the turning code to work tile by tile for this, and it turns a picture more than five times faster than the code a single layer's 90 degree rotation used before, so that got quicker too.
One more that was asked for a while ago: the side panel can be wider. Drag its left edge, double click it to get the default back. Every tab shows the same width, and Scumble remembers it.
Honest notes. Straightening by an arbitrary angle, drawing a line along a horizon that should be level, isn't in yet, and neither are crop presets with thirds and golden-ratio overlays. Straightening means resampling every layer, and doing that on a picture bigger than a browser canvas takes a different approach than the one Scumble uses for a layer's own rotation, so it gets its own release. And the undo step of a turn keeps the old pixels, the way crop and resize already do. On a very large picture that's a few gigabytes until the step drops out of the history.
Next up: straightening and crop presets, then the brushes.
· v0.1.30
Save it, and it stays
Scumble has its own file format now, so a document opens again exactly the way you left it. PNG exports stop carrying your prompt unless you ask, and TIFF finally opens and saves.
Release on GitHub ↗Until now, saving in Scumble meant exporting a picture. The layers, the masks, the text you could still edit, the filters, the selection, the prompt: all of that lived in the session, which comes back at every start, but you couldn't hand it to anyone or keep it in a folder next to the project it belongs to. Now you can. Ctrl+S saves a .scumble document, and opening it again, here or on another machine, gives you back everything the way you left it, fonts you added included.
That moved a shortcut I had used for a year: Ctrl+S used to export the picture. It saves the document now, like in every other editor, and the export went to Ctrl+Shift+E. A tab with unsaved changes gets a star, closing it asks, a saved one just closes, and Ctrl+Shift+T brings back the last ten tabs you closed. File, Open Recent, a double click on a .scumble file or dropping it on the window all open it. When a document already has a history of results, Save As asks whether that history should go along, because those results carry the prompts of earlier runs, and that isn't always something you want to pass on.
The format is a plain zip, so any zip tool can look inside. A save writes a new file and only swaps it in once it's complete, so a crash or a full disk halfway through leaves the old file untouched. I tested exactly that: killing the app in the middle of a save, filling the disk, cancelling. On a 15,000 by 10,000 picture with four layers, the save itself takes about half a second once the layers are stored.
While I was reading the export code for this, I found something I didn't like. Every PNG Scumble exported carried the prompt, the negative prompt, the seed and the recipe as text inside the file. Anyone you sent a picture to could read what you had typed, and a recipe imported from your own ComfyUI workflow carried every setting of that workflow, file names and paths included. Now a PNG carries none of it unless you tick Prompt and recipe in the PNG in the Export panel. JPEG, WebP, PSD and ORA never carried any of it. PNGs are also marked as sRGB now, which their colours always were.
And TIFF. The Open dialog has offered TIFF files since the beginning and then failed on every single one, because the browser engine inside Scumble can't read them. Now it does: 8 and 16 bits, RGB, grayscale and palette, the common compressions, with transparency, and TIFF is an export format too. I looked at the existing libraries first, and every one of them decodes a whole strip of the file at once. Lots of TIFFs are stored as one single strip, so on a 15,000 pixel picture that means holding the whole thing in memory in one piece, which is exactly what Scumble is built to avoid. So the reader streams inside the strip instead. A 15,000 by 10,000 test picture exports in about four seconds and comes back byte for byte.
A small one from the same test: on the older of Scumble's two drawing engines, that big TIFF came out up to two levels off in a quarter of its pixels. The cause was one setting in a helper that copies a very large picture band by band: with image smoothing left on, a same-size copy isn't quite a copy. That helper also fed the PSD export in a rare case, so that's fixed too.
Honest note: the double click on a .scumble file is set up in the installer, but I haven't watched it work on an installed copy yet, and TIFF files from Photoshop, Affinity or Lightroom have only been checked against what Python's imaging libraries write. Tell me if one of yours doesn't open.
Next up: a history panel with your undo steps as a list, and masks that stay masks when a PSD goes to Photoshop and back.
· v0.1.29
Close it, it waits now
Closing Scumble no longer loses your last strokes, a crashed window comes back with your documents, the app can wear skins, and Magnific and Oxen.ai join as providers.
Release on GitHub ↗This one grew out of a long list. I sat down with everything Scumble can't do yet compared to the editors people actually use for retouching, and it came out at somewhere between sixty and a hundred working days. So it's being built in pieces now, one after the other, and this release carries the first three.
The one I'm happiest about is also the least visible. Scumble saves a changed layer 15 seconds after your last stroke, so painting stays smooth on huge pictures. But closing the window didn't wait for that, and neither did installing an update. Paint something, close right away, and the next start brought the document back without those last strokes, or without a layer you'd made in those seconds. Nobody reported it; it turned up while reading the code. Now closing waits until everything is saved. That's a fraction of a second on a normal picture and a second or two on a 15,000 pixel one, and if you close again while it's saving, it asks whether you want to wait. An update's installer starts only after the save.
While I was in there: if Scumble's window crashes (a very large picture can run it out of memory), it now comes back by itself with your documents. If it crashes again right away, it starts empty instead of looping, and keeps the documents aside. Settings, Local files, Earlier states opens them again as tabs, and the same list has the documents of your last two sessions, for the day a start doesn't bring back what you expected. Testing that turned up a nasty old one too: after a crash, the log tried to tell the dead window about every new entry, failed, logged the failure, and tried again. Two crashes made 1.4 MB of log. That's gone.
Then skins. Scumble can change its whole look now: Settings, Appearance, or View, Skin. Two come with it. 90s is a late-nineties media player, bevelled slate panels, green LCD readouts, small type. Duck is warm cream, lavender and orange, soft and rounded, after a little robot I like. A skin is just a folder with a stylesheet and no code, so anyone can make one, and docs/SKINS.md says how. Under the hood that meant replacing every hard-coded colour in the app with one of 37 named tokens, and proving afterwards that the default look didn't move by a single pixel.
One part of a skin gets extra care: the assistant's question before it spends your money. A skin must never be able to hide it, fade it or swap its buttons. My first version checked that the question was visible and switched off any skin that hid it. A review then found two ways past the check: paint over it with a giant shadow, which doesn't count as covering, or shrink the chat a few seconds after the check. So now the question draws itself in a place no stylesheet can reach, above everything else on the screen, and the check keeps running while the question is open. Both tricks are in the tests now.
And two providers. Magnific grows from two upscalers into a full provider: FLUX.2, Seedream, GPT Image 2 and 2.5 and Z-Image through your Magnific key, plus recipes of its own, Mystic for Generate new, Ideogram Inpaint with a real mask, and outpainting with Image Expand. Oxen.ai is new: one key for twenty recipes, including Qwen Image 2.1, which only runs there, and a few models for prompt upsampling and the assistant. Honest note: both are written from their documentation, and none of it has run against the live APIs yet. Magnific bills every API call in credits, whatever your web plan says.
Next up is the rest of the documents work: Scumble's own file format that opens again fully editable, a history panel, TIFF, and masks that stay masks in PSD.
· v0.1.28
One key, sixteen models
Comfy Router runs sixteen of Scumble's recipes on the Comfy key and credits you may already have, without a Comfy Cloud plan. Plus Tencent's new HY Image 3.5.
Release on GitHub ↗Comfy launched something new this week: Comfy Router, a direct API for the partner models it already bills through ComfyUI's API nodes. Same Comfy key, same credits, but no workflow around it and, unlike Comfy Cloud, no paid plan. That was too good to leave for later, so this release is mostly about it.
Sixteen of Scumble's recipes can run on it now: GPT Image 2 and 2.5 (with your selection as a real mask), Nano Banana 2, 2 Lite and Pro, FLUX.2 pro and max, FLUX.1 Fill, Seedream 5.0 Lite and Pro, Qwen Image 3.0, Magnific Precision as an upscaler, and Grok Imagine, Ideogram 4 and Krea 2 for Generate new. It's always the last option in a recipe's provider list, so nothing you're used to changes. There's no new key field either: Comfy Router uses the key you put in the Comfy Cloud row.
The Router sends every model its own native request, so there's no one format to learn, there are nine. I didn't want to guess at any of them, so I downloaded the published schema of every model Scumble sends to and made the tests check every request against it, field by field. Runs go into Comfy's queue and get collected when they're done, and every run carries a key that makes a resend safe: if an answer gets lost on the way and Scumble asks again, Comfy hands back the first run instead of starting and billing a second one.
Then I tried it for real. GPT Image 2 painted an apple into a selection in 24 seconds for about three cents, Nano Banana 2 a potted plant in 16. The first key I pasted didn't work at all, by the way: it wasn't a Comfy key, and the Router said so on every route. Easy to check before spending anything, because listing the models costs nothing. The rest of the models haven't had their live run yet, and their notes say so.
And one model that isn't on the Router: HY Image 3.5 Preview, Tencent's new image model, which ComfyUI added as partner nodes a day earlier. Scumble talks to the same route those nodes use, with the same key. It edits with up to five pictures (name them @Image1, @Image2 in the prompt, like in ComfyUI) and does Generate new. My test edit, a coffee cup, took 28 seconds and cost exactly the $0.034 the ComfyUI node says it does. One honest warning: that route isn't a published API, it's what ComfyUI itself sends, so a change on Comfy's side can break it before I catch up. The recipe note says that too.
That $0.034 also cleared up a mystery: Comfy's balance endpoint answers in a field called micros, but it went down by exactly 3.432 for that run. So it counts cents, whatever the name says.
I also started a list of what comes after the Mac: making 3D objects with AI models and dropping them in as 3D layers, which Scumble can already render and turn. The Router has a few 3D models; whether their results are good enough to paint over is the first thing to find out.
· v0.1.27
Ask the manual
Press F1 and the manual opens next to your picture, with a chat that answers from it. Plus a logo, a prompt field for the upscalers, and an installer that stopped carrying my whole project folder around.
Release on GitHub ↗Until now, Help › Editor guide opened the README of the ComfyUI node on GitHub. Wrong file, wrong repository, and not much help for a desktop app. So this release replaces it with the real thing: press F1, or the new Help button in the top bar, and the manual opens in a column next to your picture. It's the same manual as on this website, all 17 chapters, searchable, and it works offline.
Above the manual sits a chat. Ask it how to do something and it answers from the manual, and only from the manual, then names the chapter it took the answer from. One click and you're reading that chapter. I tried it on a real model with a question the manual doesn't answer (how to sync settings between two computers), and it said so and pointed me to the docs instead of making up a menu item, which is exactly the one thing a help chatbot must not do. It runs on any model you have a key for, including the small text-only ones, because it needs no eyes and no tools. It also can't change anything in the app; that's the assistant's job. With a small model through OpenRouter a question cost me about one cent.
The bigger change is behind the scenes: the manual used to live only in this website's code, which meant it would slowly drift away from the app it describes. Now it lives next to the code in the Scumble repository, and this page is built from a copy of it. A few checks make sure it doesn't name things the app doesn't have: every shortcut in the menus has to be in the shortcut list, and every settings section or menu item the manual mentions has to exist. They caught two mistakes on their first run, one of them mine from the same afternoon.
Scumble also has a logo now: a little creature made of paint, with a chalk brush stroke behind it that shows through its body. That's what a scumble is, a thin half-transparent layer over a dry one. At 16 and 24 pixels it gets its own simplified drawing, because the full one turns to mush that small.
The Upscale dialog has a prompt field now, for the two upscalers that take one (Clarity and Magnific Creative). They always used the prompt from the Generate tab, but the dialog didn't show it, so it looked like you couldn't give them one.
And an embarrassing one. In 0.1.26 I made the installer smaller by telling the build what to leave out. Turns out that when you only tell electron-builder what to leave out, it starts from everything, so 0.1.26 packed my whole project folder into every install: the development docs, the tests, the Rust sources, the build scripts. Nothing private, and nothing the app ever read, but it was about 5 MB of junk on your disk. The installer is 128 MB now, and there's a check that stops it from happening again.
One more honest correction: the recipes that run through OpenRouter all said they had never been tested against the live API. GPT Image 2.5 Flare and Sunburst have now done well over a hundred real edits through it, so those two say so, and the other models say the route works but that model hasn't been tried yet.
Next up is the Microsoft Store. The package is built and has run installed on my machine, and a Store copy gets signed by Microsoft, so no more SmartScreen warning for whoever installs it from there. The GitHub installer stays as it is.
· v0.1.26
Smaller, and on Linux
The Windows installer lost 54 MB, Scumble comes for Linux now, and it needs a proper logo before it goes to the Mac.
Release on GitHub ↗The third release today, and the unglamorous kind: nothing new in the editor, it's all about how Scumble gets onto your machine.
The Windows installer was 188 MB. Turns out a good chunk of that was stuff a Windows PC never touches. The runtime for the helper models (SAM2 and background removal) comes with builds for macOS, Linux and Windows on ARM, and all of them went into every Windows installer. So did Chromium's interface texts in 55 languages, even though Scumble's own menus and dialogs are English anyway. Now it only packs the Windows x64 runtime and English plus German. The installer is down to 134 MB, and the installed app from 676 to 421 MB. I checked that the helper models still load from the smaller package, on the GPU and on the CPU.
And Scumble comes for Linux now. This release has an AppImage and a .deb next to the Windows installer, and so will every one after it. The AppImage updates itself like the Windows app does. Honest note though: I haven't run it on Linux myself, I don't have a Linux box at hand. So it's built, not tested. If you try it, tell me what breaks. On Linux the helper models run on the CPU for now, because the GPU runtime would have added a few hundred megabytes to the download.
Two small things came with it. If your Linux desktop has no keyring, the API keys would only be obfuscated, not really encrypted, and the settings now say so in plain words instead of pretending everything is fine. And the MCP registration you can copy from the Help menu points at the AppImage file itself. Everything inside an AppImage moves to a new place every time it starts, so any other path would have stopped working the next day.
The Mac comes next, but not yet. Scumble's icon is a 512 px picture with no source behind it, and a Mac wants a 1024 px icon. Instead of blowing up the old one, Scumble gets a proper logo first. The name already has the idea: a scumble is a thin, half-transparent layer of paint over a dry one, so the one underneath still shows through. That's exactly what an inpaint result over your picture is. Once the logo is there, the macOS build follows.
· v0.1.25
Layers in, layers out
PSD and ORA files open with their layers now, layer names with umlauts survive the PSD export, and upscaling runs on your own ComfyUI too.
Release on GitHub ↗This one started as a bug report of my own: Scumble could save a PSD with all its layers, but not open one. Turns out it wasn't a broken path, there simply was none. The open dialog didn't even list .psd, and a PSD you dropped in went straight to the browser's image decoder, which has no idea what to do with it.
Now Open, drag and drop and the load_image command read Photoshop PSDs and OpenRaster ORAs as layers: names, positions, opacity, visibility and blend modes. If the bottom layer covers the whole picture, like Photoshop's Background or anything Scumble saved, it becomes the picture. Otherwise the picture is transparent and every layer stays a layer. Drop a PSD on a picture that's already open and its layers get added where the file has them.
Photoshop has things Scumble has no place for, so here's what happens to them. Layer masks get baked into the layer's transparency. Groups get flattened, and their visibility and opacity carry over to the layers inside. Adjustment and fill layers are left out, clipping masks aren't kept, and blend modes Scumble doesn't have become normal. The status line lists all of it, so nothing disappears quietly. RGB and grayscale, 8 and 16 bit work. PSB, CMYK and 32-bit files get refused with the reason.
I tested it on real Photoshop files from my own projects, with groups, masks and hidden layers. Stacked back up, the layers match Photoshop's own merged picture to within a fraction of a level. The only real difference came from files where a gradient fill layer was the background, and those say so when they open.
Writing the test for this turned up a bug in the other direction: the PSD export wrote every layer name as plain ASCII, so a layer called Gürtel came out as G_rtel, in Photoshop too. Both PSD writers now also store the full Unicode name, the way Photoshop does.
Upscaling got a local route too. There's a new recipe, Upscale model (ComfyUI), that runs any upscale model from your server's upscale_models folder: ESRGAN, UltraSharp, DAT, whatever you've got. It works on the selection. The box goes out at its native size, without a fill or reference layers, and the model's bigger answer gets fitted back in as a sharper layer. The whole-picture mode isn't offered here, because the node's stitch can only paste back into the box. It hasn't done a run on a real server yet.
And the upscalers from 0.1.24 have now run for real with my own keys. Topaz Precision through fal took about 25 seconds for a selection and for a whole 2 MP picture, and 34 seconds to take that picture 4 times larger to 33 MP. Magnific Creative took 13 seconds. Magnific Precision took five minutes for a small box, so the status line now warns you about that, the same way it does for Topaz.
· v0.1.24
Make it bigger
Scumble can upscale now: a selection as a sharper detail pass, or the whole picture 2, 4 or more times larger, with Topaz, Magnific, Clarity, SeedVR2 and Recraft.
Release on GitHub ↗There's a new Upscale button next to Generate new. It opens a small dialog: pick a model, pick the factor, and decide whether it works on the selection or on the whole picture.
On the selection it's a detail pass. The selected area goes to the upscaler at its own size, the sharper answer comes back and gets fitted into the selection at the document's resolution, as a new layer. Nothing gets bigger, it just gets crisper. Generate does the same thing while an upscale model is the selected recipe, so picking one from the recipe list is never a dead end.
On the whole picture the base image goes out and the answer becomes the new picture, 2, 4 or more times larger. Every layer, every mask and the selection are scaled along, and one Ctrl+Z takes all of it back. Pictures over 4096 px on the long side are refused before anything is sent. For those, upscale a selection. Doing whole huge pictures in bands comes later.
Nine models, in their own Upscale group of the recipe list. Through fal.ai, so no Topaz account needed: Topaz Precision, Bloom and Wonder, the open Clarity upscaler (your prompt guides the added detail), SeedVR2, and Recraft Crisp and Creative. Through Magnific, with a new key row: Magnific Precision (2 to 16 times) and Magnific Creative (2, 4, 8 or 16 times, prompt as guidance). Both Magnific upscalers and both Recraft ones also run on Comfy Cloud, billed in Comfy credits.
Two things to know. Topaz can take several minutes on a large picture. The status line tells you, and the window stays usable while it runs. And every Magnific API call costs credits, even if your web plan says unlimited. That allowance only covers their own web app.
Agents and the built-in assistant get an upscale command too. The assistant asks before it upscales, same as before it generates. Honest note: I wrote every one of these from the providers' docs and schemas, and none of them has done a real run against a live API yet. I'll be testing them with my own keys over the next few days.
· v0.1.23
Where did the layer names go?
Layer names are back and can be renamed, Qwen Image Edit 2.1 runs on your own ComfyUI, and prompt upsampling learned to upscale.
Release on GitHub ↗A small patch, and the first one that started as a GitHub issue. You couldn't rename layers. Turns out the rename was never broken: a layer row was about 15 px wider than the panel, and the name was the only thing in the row that gave way. It got squeezed down to zero pixels. So you saw the eye, the thumbnail and the IMAGE / RESULT dropdown, but no name to double-click, the delete button was cut off, and the whole list scrolled sideways.
The panel on the right is 320 px wide now instead of 290, the row's buttons are a bit more compact, a name always keeps at least 48 px, and the rows of a text layer wrap instead of running off the edge. Double-click a name to rename it, like the tooltip always promised. And renaming is an undo step now, so Ctrl+Z brings the old name back.
New local recipe: Qwen Image Edit 2.1 (ComfyUI), built from ComfyUI's own template. One thing I found while wiring it up: Qwen's text encoder only reads the first picture of each input, so if you plug Scumble's crop batch straight into it, your reference layers quietly disappear. The recipe splits the batch instead: the crop is <image1>, the next two pictures (the Original copy, your reference layers) are <image2> and <image3>. It needs a current ComfyUI and the three Qwen Image 2.1 model files, and the recipe lists where to get them. I checked it against a real ComfyUI's node definitions, but it hasn't done a real run yet.
And there's a new upscale use case for prompt upsampling. Pick it next to the Upsample button and the language model describes what's already in the picture, plus the fine detail an upscale or refinement pass should bring out, and it's told not to add, remove or change anything.
· v0.1.22
Bring your own language model
Any model from any provider, for the assistant and for prompt upsampling. And the model picker stops warning about itself.
Release on GitHub ↗A short one, same evening as 0.1.21. My list of built-in models is curated, but I kept wanting to try models that weren't on it. So now there's Settings › Language models: pick a provider, type the model id exactly the way that provider spells it, tick what it's for, done.
Tick Prompt upsampling and the model shows up in the editor's Upsample list. Tick Assistant and it appears in the chat's model picker, in its provider's group. It runs on the key you've already stored for that provider, so there's no new key to set up. If the model can't see images, untick Can see the picture: it'll never be sent the crop, and the assistant leaves its screenshot tool out.
For OpenRouter, the id field suggests from their live list of models that can use tools, so a model they add today works today, without a Scumble update. DeepSeek, Moonshot, Z.ai and WaveSpeed can do prompt upsampling now too. Until now their keys were only used by the assistant.
Fair warning: nothing checks whether the id exists or whether the model understands tools. That's between you and the provider, and whatever error they send back is what you'll see.
And something that had been bugging me: every row in the assistant's model picker said “not tried with a real key”. Ten providers, every single row. It read like the app was warning you about itself. That's gone. A row now says only what's actually true about that model, and the honest note that no model has finished a task against a live API yet is written once, in the docs and in the release notes.
· v0.1.21
Scumble gets an assistant
A chat column that drives the editor, plus OpenRouter and BytePlus as new providers.
Release on GitHub ↗This is the big one. There's now a chat column on the right: the Assistant button in the bar, View › Assistant, or Ctrl+Shift+A. You tell it what you want and it does it with the same commands an external MCP agent gets. It selects, adds layers, writes the prompt, renders, colour-matches and exports, and every step shows up as a card so you can watch what it's doing.
It runs on your own API key, across all four model families: Anthropic (Claude Sonnet 5, Opus 5), OpenAI (GPT-5.6 Terra, Sol, Luna), Google (Gemini 3.8 Flash, 3.1 Pro preview, 3.5 Flash-Lite) and anything that speaks the OpenAI chat format: OpenRouter, DeepSeek, Moonshot / Kimi, Z.ai / GLM, ToAPIs, WaveSpeed or your own local server.
I spent a lot of time on keeping it from going rogue. Anything that costs money or puts work on your ComfyUI asks first: generate, select by text, cutout, upsampling. So does anything that clears your undo history or bakes layers together, and any edit to a layer it didn't make itself. Neither button on those cards is the default, and pressing Enter in the chat never answers one.
Everything it does can be taken back. Ctrl+Z undoes each of its steps, including the ones the editor normally doesn't record. When a turn is finished, Undo this turn puts every document it touched back the way it was (pixels, selection, prompt, settings), even if the turn was longer than the undo stack. That one needs the tile engine. Chats are saved and can be reopened, and Settings › Assistant has one button that deletes everything the assistant ever stored. Your API keys stay.
What leaves your machine: your messages, a short note about the open documents (names, sizes, layer names), the results of its tool calls and any screenshots it takes. All of it goes to the provider you picked and nobody else. Where things stand: every model family was built from its docs and checked against the real servers as far as a key without credit lets you. No model has finished a real task yet. That's what my bug hunt after this release is for.
Also new: OpenRouter as an image provider (one key for GPT Image, Nano Banana, FLUX.2, Seedream, Grok Imagine, Krea and Recraft) and BytePlus ModelArk, which runs Seedream 5 straight from ByteDance. Both are opt-in, nothing moves over on its own. OpenRouter is told to skip every host it lists in China, and BytePlus runs in Malaysia or Dublin. Neither has been tried against the live service yet.
Two fixes I'm a little embarrassed about: FLUX.2 [flex] on fal ran with 2 steps instead of 50, because two settings rows were sharing one slot. And you couldn't import a recipe with several providers, which is the format of every recipe I ship. Both fixed.
· v0.1.20
No more freezing on big files
Large JPEGs open in the background, API runs stop locking the window, and letting go of the brush is smoother.
Release on GitHub ↗This one is all about that moment when the window just stops. I work on 15k images a lot, and three things kept freezing it.
Opening a large JPEG, a WebP or a PNG with a colour profile used to lock the window for one to four and a half seconds while the browser decoded it. Now a background worker does that, and the window stands still for well under a tenth of a second. A JPEG with an Adobe RGB profile went from 3.7 seconds of freeze to 0.03. Same pixels as before, with the colour profile, EXIF rotation and transparency.
API runs: cutting out the crop and stitching the answer back in held the window for up to 6.3 seconds on a 15k document with a colour-matched layer and a film look. Now it's 0.05. All of that happens in the background, from the same picture.
And letting go of the brush or eraser on a huge layer: the hitch went from 0.29 seconds to 0.07. The stroke is now written tile by tile instead of through giant temporary pictures. Soft paint can come out one level different, which you can't see.
· v0.1.19
Colour-matched layers catch up
Saving and the magic wand are as fast with a colour-matched layer as without one.
Release on GitHub ↗Colour match per layer is one of my favourite things in Scumble, but it had a price: any document with a matched layer took the slow path when you saved it or used the magic wand. Not anymore. The background workers now read the match statistics straight from the picture's tiles and apply the match themselves.
On a 15000 × 10000 picture with a big matched result layer, a PNG export went from 6.4 seconds to 1.8, and the window freezes for 0.08 seconds instead of 1.4. The magic wand went from 2.5 seconds to 0.9.
The honest part: a matched layer's colours can shift by a few levels in exports, because the statistics now come from samples of the picture instead of the whole picture drawn small. I measured it on four photos: 0.1 to 2 levels on average, 7 at most on a very textured landscape. You won't spot it, but I'd rather you know.
Also fixed: set_layer with match_source “below” was quietly treated as “surroundings”, so an agent couldn't pick the other source. And I moved some of the editor's plumbing into files of its own. That changes nothing for you, but it makes my life easier.
· v0.1.18
Twice as fast, again
Filter layers, blend modes, big PNGs, selections and the magic wand all move to the background workers.
Release on GitHub ↗A big performance release. The idea behind all of it: stop pushing every strip of a huge picture through the browser's canvases, and let the background workers and the graphics card do the work directly.
Documents with filter layers save about twice as fast. A 15k picture with three paint layers and a levels layer went from 6.2 seconds to 1.4 for a PNG. Blend modes (multiply, screen, overlay and friends) now run in the workers too, and they're calculated more precisely than before. The magic wand and the bucket are about three times as fast on large pictures, and they select exactly the same pixels.
Opening a big plain PNG no longer freezes the window (2.1 seconds down to 0.1). Grow, shrink and feather on a large selection hardly hold the window anymore. And the soft masks that blend an API result into your image take 0.6 seconds instead of 2.5.
Pixels can be one level different here and there, where layers are partly transparent. The browser's own canvases disagree with each other by more than that.
· v0.1.17
Pictures bigger than the browser allows
600-megapixel PNGs open, saving no longer freezes the window, and whole-picture filters stay put when you zoom.
Release on GitHub ↗Chromium can't hold a canvas bigger than 268 megapixels, so until now neither could Scumble. Now a PNG that big is read piece by piece straight into the tile engine. A 30000 × 20000 file (600 megapixels, 1.1 GB) opens in about ten seconds, and you can pan, paint, select, render and undo like with any other picture. The new limits are 65,535 px per side and one gigapixel. Pictures that size save as PNG, PSD or ORA. JPEG and WebP need one canvas of the whole thing, and Scumble tells you so instead of writing an empty file.
Saving doesn't freeze the window anymore either. A PNG is now written in strips, up to eight workers compress them at the same time, and a progress figure counts up in the status line. On a 15k picture the whole save actually takes a bit longer than before, but you can keep working while it runs, and the files are less than half the size.
A bug that had annoyed me for a while: vignette, Normalise, and the film pack's frame, light leak and halation were calculated on whatever part of the picture you were looking at. Zoom in and the vignette darkened the corners of your view, not of the image. Now they're placed in the whole picture, so the screen matches the export.
Also: faster PSD and ORA export, a lighter autosave, and plugins can now place their filters relative to the whole picture.
· v0.1.16
Rust under the hood
Pixel work in WebAssembly, and a colour-matched layer no longer eats a gigabyte.
Release on GitHub ↗Grow, shrink, the magic wand, the bucket and the picture's detail levels now run as compiled Rust (WebAssembly) instead of JavaScript. The results are identical to the last bit, just faster: a magic wand across a whole 15k picture went from 4.6 seconds to 3.1. If the compiled code can't load for some reason, the JavaScript takes over as before.
The bigger win: a colour-matched layer used to be matched on a full-size copy of itself every time the view looked at it. On a 15k picture that was 1.1 GB of memory and a sluggish pan. Now only the part you see is matched, straight from the tiles: 0.13 seconds for the first frame, 3 ms per frame while panning, and no copy at all.
Also in here: the screen, the navigator and the eyedropper now agree on what a matched layer looks like. Cropping, resizing and flattening no longer decode the whole picture again, and their undo steps are much lighter. Brush strokes keep less in the undo history too.
· v0.1.15
Unfreezing the small stuff
The film looks panel, agent screenshots and the object tool stop stalling large pictures.
Release on GitHub ↗Half a second after every change, the Film looks panel makes a small preview picture for its thumbnails. On a 15k document it built that on the thread that draws the window, so everything froze for half a second, every single time. Now a worker does it: the window is held for 47 ms instead of 700.
Same story with the screenshots agents ask for and the picture a language model sees when you upsample a prompt. They're at most 1024 px wide, but they were made from the full document: around 2 seconds and 1.7 GB each time. Now it's 0.1 to 0.7 seconds. The object tool and background removal start much faster too.
Also fixed a sneaky one: right after a change, the eyedropper could pick a matched layer's original, unmatched colour, and from then on the magic wand and the film thumbnails saw that layer unmatched as well.
· v0.1.14
Oops, and hello ToAPIs
Painting shows the stroke again, Settings closes again, and ToAPIs joins as a provider.
Release on GitHub ↗The embarrassing part first: in 0.1.13 you only saw the first dab of a brush stroke while painting, and the rest appeared when you let go. The stroke itself was always right, only the screen didn't redraw. Fixed, same evening. Also fixed: the Settings dialog wouldn't close, because the Tile atlas box didn't accept its own default value. Yes, really.
New: ToAPIs as a provider. One key runs GPT Image 2 and 2.5, Nano Banana, FLUX.2, Seedream 5 and Qwen Image 3.0. There's a Channel setting: official is the model maker's own cloud, vip and standard cost a fraction of it. Nothing moves to ToAPIs on its own, and it hasn't been tried against the live service yet. Two things to know: your crop is uploaded to public ToAPIs file addresses for the run, because that's how their API works, and the key link carries my referral code.
With a ToAPIs key you also get cheap prompt upsampling, about a tenth of a cent per rewrite.
And switching models now starts from that model's own defaults, instead of carrying over a setting with the same name from the model before.
· v0.1.13
The tile engine is on
Every layer now lives in 256 px tiles, and the screen only draws what you can see.
Release on GitHub ↗This is the release I'd been working towards for days. Scumble now keeps the picture, every layer, every mask and the selection in small 256 px tiles, and the screen only draws the tiles that are visible, at the zoom you see them at.
On a 15000 × 10000 picture with three paint layers, a matched result and a film look, the graphics process used to hold about 7.5 GB, much of it on the graphics card that ComfyUI wants as well. With tiles it's about 2 GB there. Panning at 1:1 takes about 3 ms a frame, a brush dab about a millisecond, and zooming back to 1:1 draws its first frame in about 20 ms instead of a second.
Layer masks cost almost nothing now (1.86 GB gone on that picture). A stroke only keeps the tiles the brush actually touched: a line across the whole picture went from 560 MB to 26. Grow, shrink, feather and invert work on the area the selection covers instead of the whole picture.
The memory moves, though: the window's own process holds more now, so several huge pictures open at once add up. Close the big tabs you aren't working on. Not everything is fast yet, and the changelog lists exactly what's still slow. If something goes wrong, Settings › Rendering › Tile engine switches it off and you're back to one canvas per layer.
· v0.1.12
Groundwork, and a pile of undo fixes
One way into the pixels for the whole editor, and the bugs that turned up while building it.
Release on GitHub ↗On the surface nothing changed here. Underneath, every place in the editor that touches pixels (several hundred of them, each doing it its own way) now goes through one interface. That's the foundation the tile engine is built on.
Rewiring all of that turned up a surprising number of bugs, mostly around undo. Undo put flipped or merged layers back wrong. Pressing Ctrl+Z quickly could leave a layer half undone. Undoing further back could bring back changes you had already undone. Opening a new picture of the same size kept the old picture's history. And an edit made right after Ctrl+Z on a large picture could simply vanish. All fixed, and Flatten can be undone now too.
Closing a tab now actually frees its memory. Before, every closed document stayed in memory until you quit, and on large pictures that was gigabytes per tab. Oops.
And a restored document keeps its selection, including after the next save.
· v0.1.11
The editor moves home
The editor's code now lives in the Scumble repository, plus the first round of large-picture work.
A quick note first: this version never went out as a download of its own. Everything in it reached you with 0.1.12 the next day.
Until now, the editor's code lived in my ComfyUI node Inpaint Canvas and was copied into the app with a list of patches. That's flipped: Scumble is the home now, and the node gets a build of it. A fix made once reaches both.
It's also the first real work on large pictures. On a 15k image a selection change held the window for 50 to 750 ms, now it's a few milliseconds. The magic wand and the bucket look at the region instead of the whole picture. A brush stroke no longer needs three canvases the size of the layer, which was 1.8 GB on that picture.
And Settings › Rendering now watches the whole graphics card, ComfyUI's models included, and releases caches when it gets tight.
· v0.1.9
Brushes, 3D objects and an AI label
Photoshop brush packs, 3D models in the picture, the EU AI label, a console, and a lot of small things.
Release on GitHub ↗Lots of new toys in this one. You can import Photoshop .abr brush packs, and they're still there after a restart. Every tip gets its own spacing and a Follow stroke option, and the eraser uses them too.
You can place 3D objects: Plugins › Place 3D object (.glb) opens a dialog with your picture as the backdrop. Turn the model, move it, set the light, place it as a layer. Then select it and run Generate with a denoise below 1, and the model paints it into the scene.
There's an AI label panel that puts the European Commission's official icon for AI-generated or AI-modified content on your picture in one click.
Smaller but handy: SVG files open, there's a Normalise filter layer, the export can put the picture in a frame, API results default to 2K instead of 1K, and layers snap to the canvas edges when you scale them. And finally there's a console (Help › Console) and a log file, so when a provider fails you can see why. Escape closes dialogs again, and the model folder scan finds the helper models' ONNX files in your ComfyUI models folder, whatever they're called.
· v0.1.8
Two nasty bugs
A layer that vanished after an unrelated stroke, and a click that left a tiny selection behind.
Release on GitHub ↗A late-night release for two bugs that really hurt.
One: an erase or brush stroke could make a whole layer disappear from the screen, even a layer nowhere near the stroke. Zoomed out, the screen draws from a reduced copy of each layer, and refreshing that copy used a Chromium drawing mode that clears the whole copy, not just the stroke's rectangle. Your pixels were always safe, only the display lost them. That's exactly why it looked like erasing took chunks out of your layers.
Two: zoomed far out, a click with the rectangle tool could leave a tiny selection behind instead of clearing it. One wobble of your hand by a single screen pixel was a dozen image pixels. And since the brush and the eraser are clipped to the selection, retouching just stopped working with no visible reason. The drag is now measured in screen pixels.
The API size row is also called Highres fix now, with choices you can read without hovering for a tooltip.
· v0.1.7
Transparent results from OpenAI
GPT Image can hand back a real cutout, and GPT Image 2.5 goes out at up to 3840 px.
Release on GitHub ↗GPT Image 2 and 2.5 can answer with a cutout, a subject on a fully transparent background. Set Background to transparent and the result layer keeps the model's own alpha channel: logos, products, objects, ready to drop over anything. Generate a new image has a transparent background tick for the same thing.
There's a Transparent asset prompt template that writes the wording the model needs for clean edges. The rest of OpenAI's image parameters are there too (file format, compression, moderation), and GPT Image 2.5 now goes out at up to 3840 px instead of 2048.
Fixed: the prompt templates were missing from Generate a new image until you had opened Settings once.
· v0.1.6
Bigger API crops, and a shape tool
API runs go out at the size each model really takes, plus a shape tool, smaller exports and seven new models.
Release on GitHub ↗I found a silly limitation: every API run sent a 1024 px crop, whatever the model could handle, because one number controlled both local and API runs. Now every model knows its own ceiling, and a new row lets you choose how it's used, including a high-res fix that sends a small selection at twice or four times its own resolution.
New shape tool (Y): rectangles with rounded corners, ellipses, polygons, polylines, Bezier curves and freehand paths, filled, outlined or both, clipped to the selection, one undo step each. Before, this took a selection and the bucket.
Export can save smaller now (a percentage or a free size, with a quality setting for JPEG and WebP), and seven more models arrived: Z-Image Turbo, Ideogram 4, Grok Imagine 2.0, Reve 2.1, Krea 2, Recraft V4 and Z-Image base.
· v0.1.5
Generate from nothing
Images from a prompt alone, prompt upsampling on your own machine, and MCP clients that finally connect.
Release on GitHub ↗Published a few minutes after midnight, which tells you how that day went.
Generate new in the top bar makes an image from a prompt alone, on your ComfyUI or through an API provider, and then you edit it like any other picture.
Prompt upsampling works with your own local model now: point Settings at Ollama, LM Studio, vLLM or anything else that speaks the OpenAI chat API, no key needed. The way the model rewrites your prompt now comes from templates, plain Markdown files you can write yourself, import and pass on.
MCP clients that follow the spec to the letter refused to talk to Scumble, because Electron writes an empty line before the app even starts. A small launcher keeps the channel clean now, and Help › Copy MCP registration puts the right setup on your clipboard.
Plus a bunch of fixes from actually using it every day: width and height in two boxes, a click deselects again, the selection outline no longer disappears on white images, and you can copy and paste whole layers between tabs.
· v0.1.4
The app got slower the longer you used it
A memory leak found and fixed, and filter layers stay on the graphics card.
Release on GitHub ↗Found a leak: every large image you opened and closed stayed in memory with all its layers. After four 12k documents, the graphics card was holding 19 GB it couldn't use for anything, and sliders were five times slower. Now the same four rounds leave 35 MB behind. The culprit was in the plugin system.
Filter layers now stay on the graphics card for the whole chain instead of going back and forth to the processor once per layer. Free VRAM releases the caches too, and background tabs let go of what they can rebuild when memory gets tight.
Also fixed two regressions from 0.1.3: painting that seemed to snap back (the stroke was there, the screen just didn't show it), and a colour-match slider that did nothing on screen.
· v0.1.3
The graphics card does the stacking
All layers are composited in one shader pass, and panning stops stuttering.
Release on GitHub ↗Every layer is now stacked in one shader pass on the graphics card instead of one at a time on the processor. With a dozen layers in a large window, the slowest frames went from about 10 ms to 0.2. I checked it pixel by pixel against the old way, across every blend mode, a masked layer, colour match and text: it agrees within one level out of 255.
Filter layers, a running brush stroke, transforms and exports stay on the old path for now, and a machine without WebGL2 works just like before.
· v0.1.2
High-res editing that doesn't hurt
The drawing pipeline rebuilt around what's actually visible.
Release on GitHub ↗Working on 6k to 12k images meant waiting after every single action. So I rebuilt the drawing pipeline around what's actually on screen. On a 96-megapixel document, the opacity slider went from 250 to 900 ms per step to under 10, the magic wand from about 2 seconds to 0.3, and saving a layered PSD from 4.1 seconds of frozen window to 0.1.
Images over 64 MB couldn't be loaded at all, because they took a route that needed ComfyUI. They're stored locally now like everything else, so loading works with no server at all.
New: prompt upsampling with your own API keys (GPT, Gemini, Claude), and presets for local recipes, so a model, text encoder and VAE combination can be saved under a name.
· v0.1.1
First fixes
Filters on huge images, and two more API providers.
Release on GitHub ↗Two hours after the launch. Filters on very large images showed one corner blown up to full size, because Chromium caps a graphics buffer at about 33 megapixels. Above that, filters now render in tiles.
Two more API providers: WaveSpeedAI and Comfy Cloud. And the provider list in Settings no longer says “no key” right after you've saved one.
· v0.1.0
Hello, Scumble
The first public release.
Release on GitHub ↗Scumble is out, free and under the GPL-3.0.
It's a standalone editor for AI inpainting that grew out of my ComfyUI node Inpaint Canvas: layers, selection by text, retouch tools, filter layers, colour match per layer, text layers, PSD and ORA export.
It renders through your own ComfyUI, on your machine or on a remote box, or through API providers. Background removal and object selection run right inside the app. There's a plugin system with a film pack of eleven looks built in, it speaks MCP so an agent can drive it, and it updates itself from GitHub.
Windows only for now, and the installer isn't signed yet, so SmartScreen will warn you on the first start: More info, then Run anyway.
About the name: a scumble is a thin, semi-opaque layer of paint over a dry one, so the layer underneath shows through. Which is pretty much what an inpaint result over your image is.